AI app for it and development · no coding needed
Test fixture privacy workbench
Constraint-valid test data with documented synthetic provenance.
Made for: Software QA teams handling customer-shaped data
What it does for you
The problem
Realistic fixtures are difficult to create without copying private records.
What it gives you
Validated synthetic test dataset
What you give it
Approved schemasnon-sensitive constraints
How it works, step by step
- Extract schema constraints
- Generate synthetic cases
- Include edge conditions
- Validate relationships
- Flag accidental identifiers
- Export fixture sets
What you see on screen
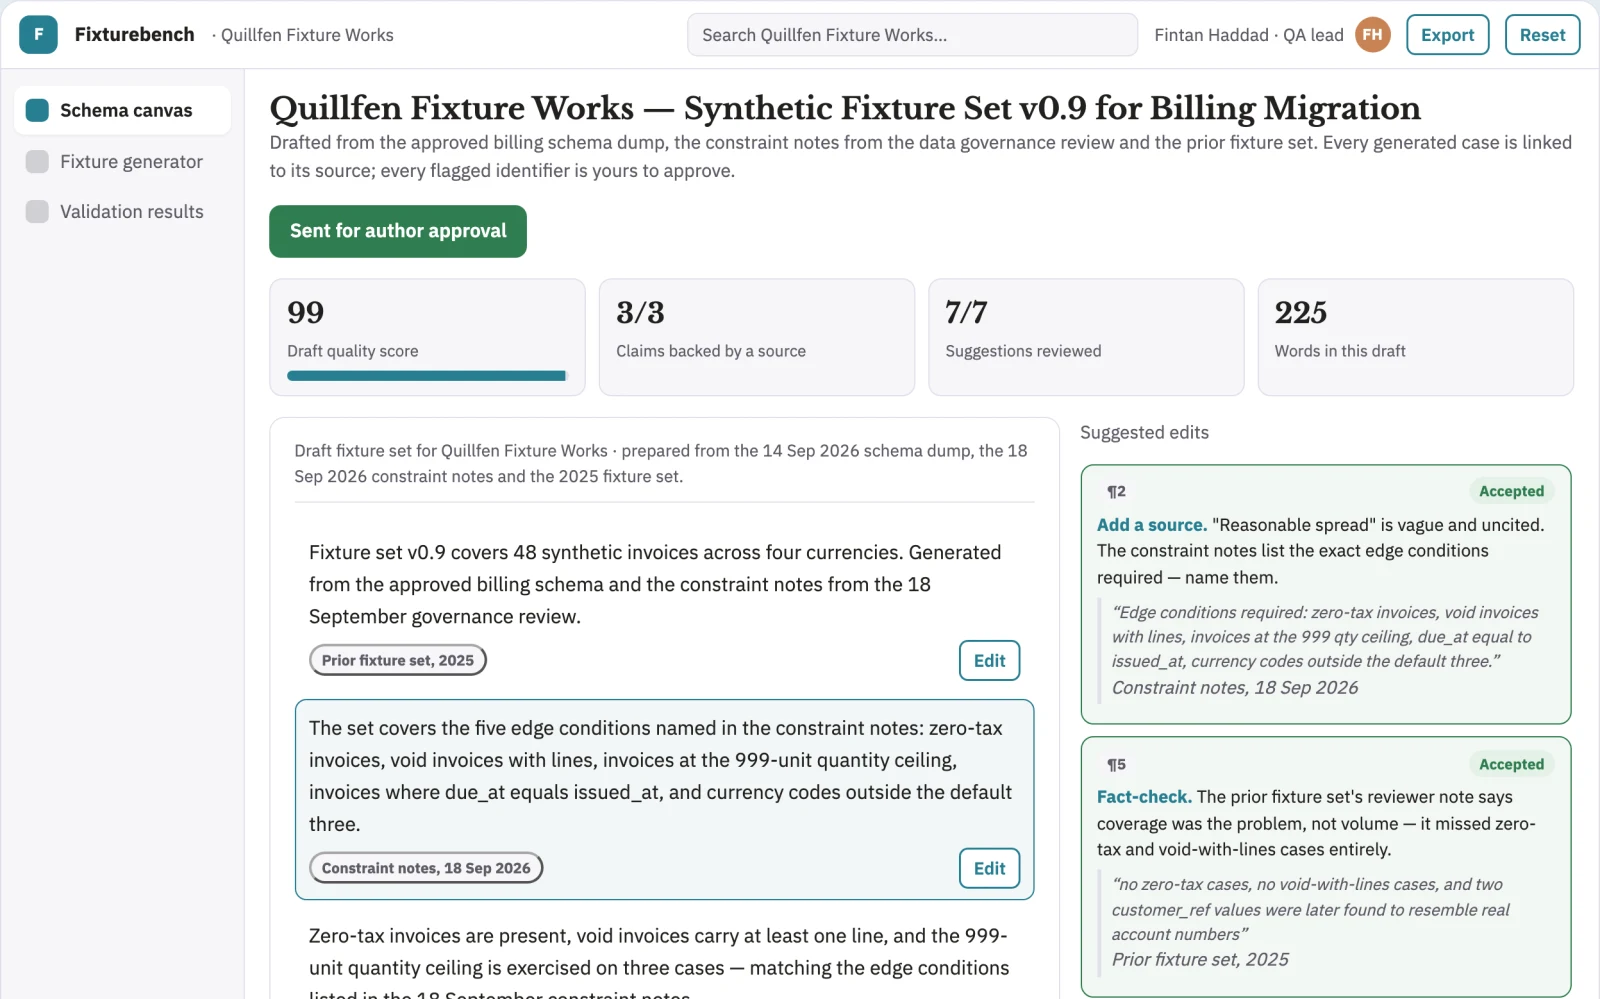
- Schema canvas
- Fixture generator
- Validation results
Build it yourself with your AI system
Build this app yourself, no coding needed
Start with a quick version you can try in a few minutes. Like it? Then build the full app by copying and pasting our step-by-step instructions: everything is prepared for you.
Sign in to see how to build it yourself
Build a quick version to try, or get the full app pack for Test fixture privacy workbench with the step-by-step building instructions. You don't need any technical skills: you copy, paste and answer a few questions. Both are included in the membership.
4 Have it built for you days to a few weeks
Rather not do it yourself, or want it fully tailored to your data, your way of working and your brand? Nexibeo builds Test fixture privacy workbench with you.
What's in the app pack
Included in the Complete AI Training membership.
- The building instructions your AI follows, step by step
- The questions your AI will ask you about your business before it starts
- A clickable demo you can open in your browser, to see how it should work
- A detailed blueprint of the screens, the information it keeps and the checks it runs
Become a member to get the app packAlready a member? Sign in
The files, for the technically curious
- START-HERE.mdHow to build it with your own AI (read first)3 KB
- README.mdOverview and links1 KB
- questions.mdQuestions to answer before you build2 KB
- prompt-cloudflare.mdThe full build prompt, hosted on Cloudflare24 KB
- prompt-vps.mdThe same build on your own server (Docker)24 KB
- spec.jsonData model, API, AI pipeline, acceptance criteria12 KB
- demo/index.htmlThe working demo on sample data200 KB
Questions
Do I need to know how to code?
No. You copy and paste the prompts on this page into ChatGPT or Claude, and the AI does the building. When it asks you something, you answer in your own words.
What does it cost?
The quick version, the app pack and the step-by-step instructions are for members: you pay the membership price, not a price per app (see the plans). Building the full app uses your own ChatGPT or Claude subscription. Putting it online is often cheap or no cost at the start, and your AI tells you before anything costs money.
How long does it take?
The quick version: about two minutes. The real app: an afternoon for a first version you can use, longer if you want every feature.
Can I change it to fit my business?
Yes. Tell your AI what to change in plain words, like “add a column for the price” or “use our logo and colours”. Or have Nexibeo build and customise it for you.
More detailsHow the AI works, safeguards and what to build first
For software QA teams handling customer-shaped data, turn approved schemas and non-sensitive constraints into validated synthetic test dataset. Address this specific problem: realistic fixtures are difficult to create without copying private records. The aim: constraint-valid test data with documented synthetic provenance. The pilot tests whether that benefit holds up against reviewer effort and real operating costs.
The buyer creates a project, supplies approved schemas and non-sensitive constraints, and confirms scope and access. Users correct extracted facts, resolve flagged uncertainties and approve the final validated synthetic test dataset before use. Retain source links and a version history for the next cycle.
How the AI works
Generate examples with deterministic relational validation. Keep model suggestions separate from verified facts. Link factual outputs to authorized input evidence and show missing information explicitly. Use deterministic checks for counts, dates, identifiers and arithmetic where applicable. A designated reviewer validates consequential outputs and signs off the delivered result.
Safeguards
Protect secrets, customer data and source code. Use controlled environments, technical review and a recoverable deployment process. Synthetic generation only; no production data training. Require appropriate access and publication approval. Preserve source material, label AI drafts and make corrections traceable. Measure false positives and missed cases alongside speed.
What to build first
Costed pilot: Synthetic generation only; no production data training. Start with one buyer organization and a bounded set of representative inputs. Implement the first two modules: extract schema constraints; generate synthetic cases. Support the third task through an assisted review queue: include edge conditions. Handle the remaining required functions manually until validated. Include input upload, source references, user correction, a reviewer approval step and export of validated synthetic test dataset. Authentication, account isolation, deletion controls and basic operational logging are included. Specialized production certification, live write integrations and broader rollout are not included unless explicitly stated.
What it can connect to
Authorized repositories, technical documentation, application APIs and logs. Approved repositories, application APIs, execution platforms and monitoring systems. Validate current API access and behavior during discovery before promising compatibility. Begin with uploads and exports of approved schemas and non-sensitive constraints. Any named system or connector is a candidate requiring current access and compatibility checks; no live connection is included by default.
The screens in detail
Show a work backlog, proposed changes and verification results. Link each item to its source configuration, code or data mapping. Provide execution logs and an owner-facing health view. Keep environments and approval states clearly separated so a draft cannot be mistaken for a live change. Open with schema canvas; move into fixture generator for the detailed task; finish in validation results for review and handoff. Show the source record, uncertainty and approval status beside each proposed output.