AI tool
Earlybird
Earlybird predicts spoken words before they are finished, reducing speech-to-text latency for voice agents. It outputs words roughly 90 ms ahead of complete utterance on audiobook speech, using a 17 MB model that runs on a CPU. This tool is for de...
About Earlybird
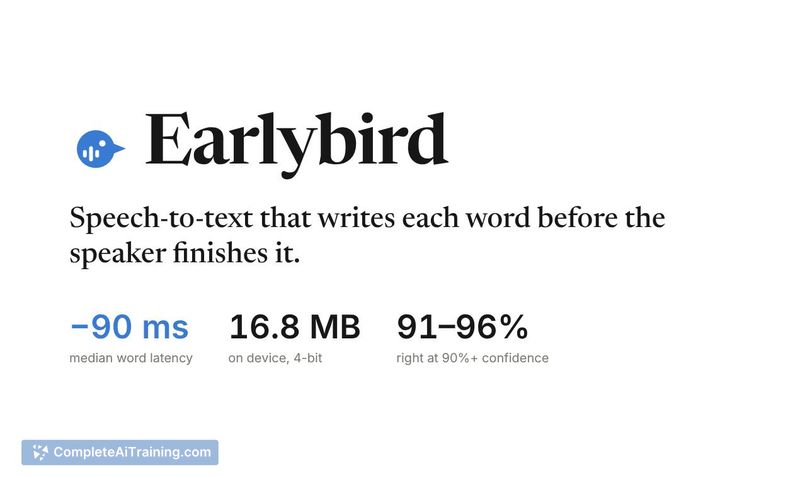
Earlybird is a 29M-parameter speech-to-text model that runs on-device at 17 MB. It predicts each word roughly 90 ms before the speaker finishes it, attaching a confidence score to every word. The model targets voice agent developers who need lower latency between speech and action, and ships with open weights and code.
Review
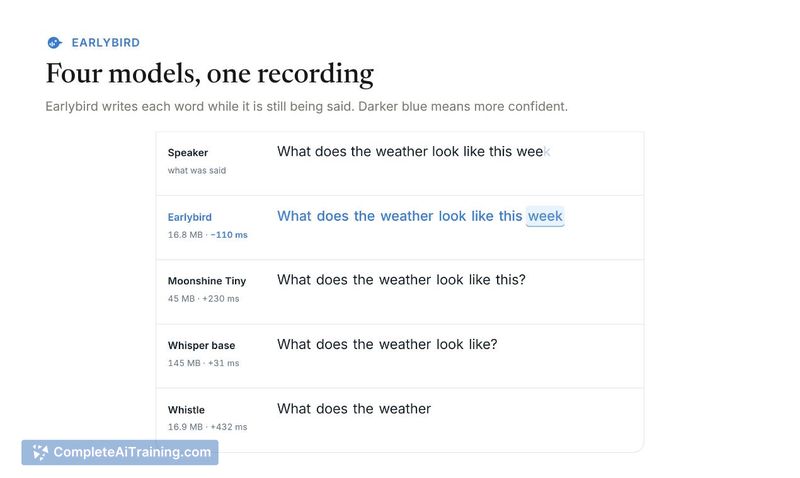
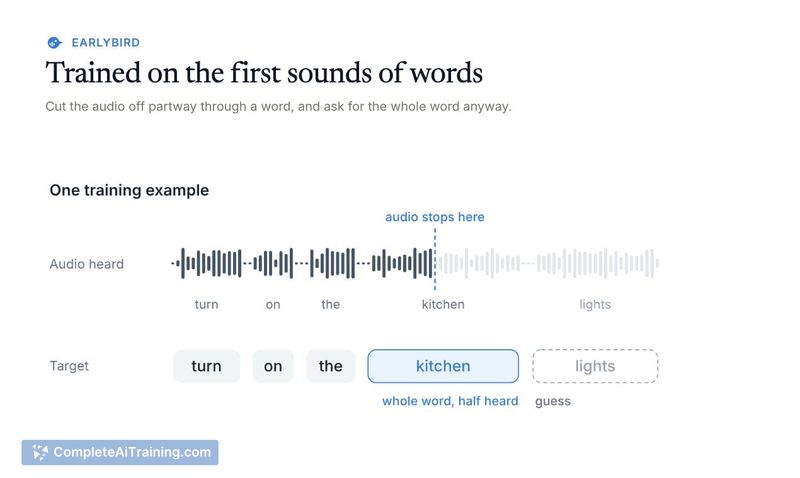
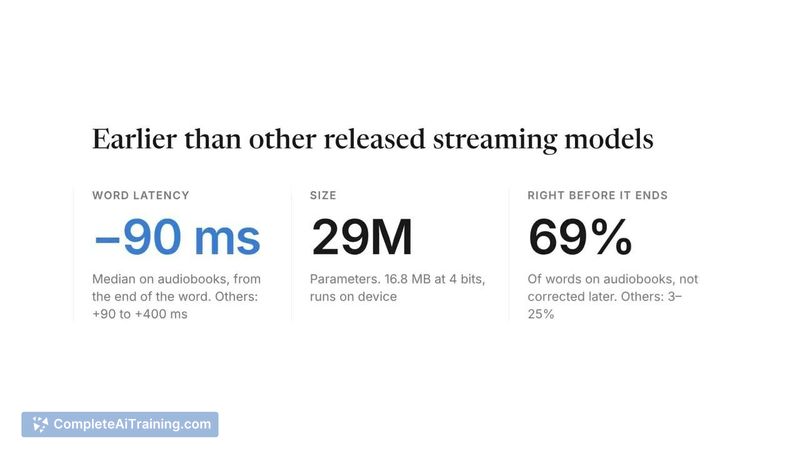
Earlybird tackles a specific bottleneck in voice agent pipelines: the lag between a spoken word's completion and its availability to downstream systems. By outputting words before they end, the model shifts the timeline earlier by a median of 90 ms on audiobook speech. That's a narrow window, but for real-time voice interactions it can affect whether a response feels immediate or delayed.
Key Features
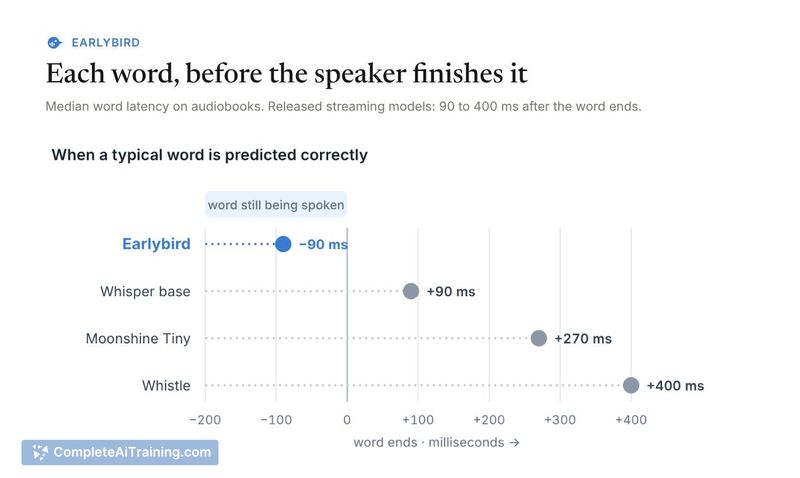
- Predicts each word roughly 90 ms before the speaker finishes it, where other streaming models typically output words 90 to 400 ms after completion.
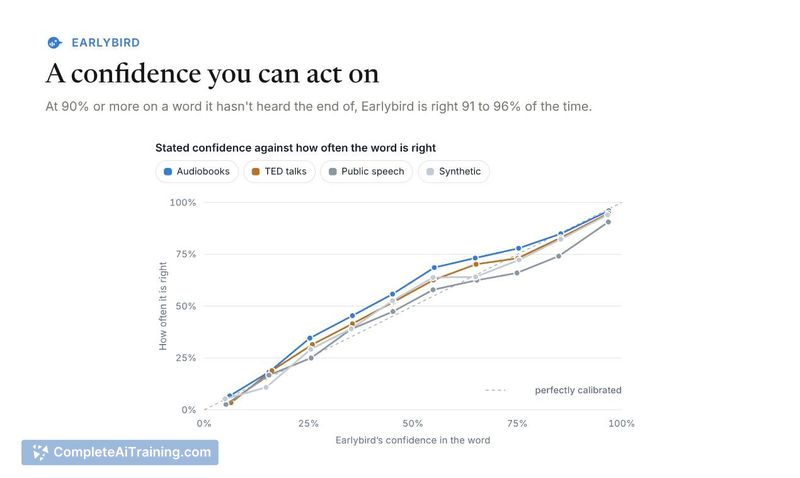
- Assigns a confidence score to every predicted word, letting an agent act on high-confidence words immediately and wait on low-confidence ones.
- Weighs 17 MB and runs on a CPU, so it fits inside applications without requiring a GPU or cloud round-trip.
- Released with open weights and code, allowing developers to inspect, modify, or fine-tune the model.
- Built specifically for voice agent use cases where earlier action matters more than perfect transcription accuracy on every token.
Pricing and Value
Earlybird is listed as free with open weights. No paid tiers, usage limits, or subscription models appear in the current release information. Pricing for any future hosted or managed version is not yet defined.
Pros
- Shrinks the time-to-text window by roughly 180 to 490 ms compared to models that wait for word boundaries.
- Small footprint makes on-device deployment practical in mobile apps or edge hardware.
- Confidence scores give developers a concrete signal for deciding when to act versus when to buffer.
- Open-source release means no vendor lock-in and full access to the model internals.
Cons
- Currently supports only English; multilingual speech isn't available yet.
- Transcription quality dips on noisy, real-world audio compared to clean recordings, as noted by the maker.
- Not well suited for applications that require high-accuracy offline transcription of completed speech, such as meeting note generation or archival dictation.
Earlybird fits best in voice agent stacks where shaving under a second off the interaction loop changes the user experience - think voice-controlled interfaces, conversational AI, or live captioning that needs to keep pace. Developers who can tolerate occasional low-confidence words and want on-device inference will find the trade-offs practical. Teams needing multilingual support or high accuracy in acoustically messy environments will want to track the roadmap before adopting.