AI agent for prompt engineers
Prompt Language Coverage Agent
One prompt that meets the quality target in every supported language
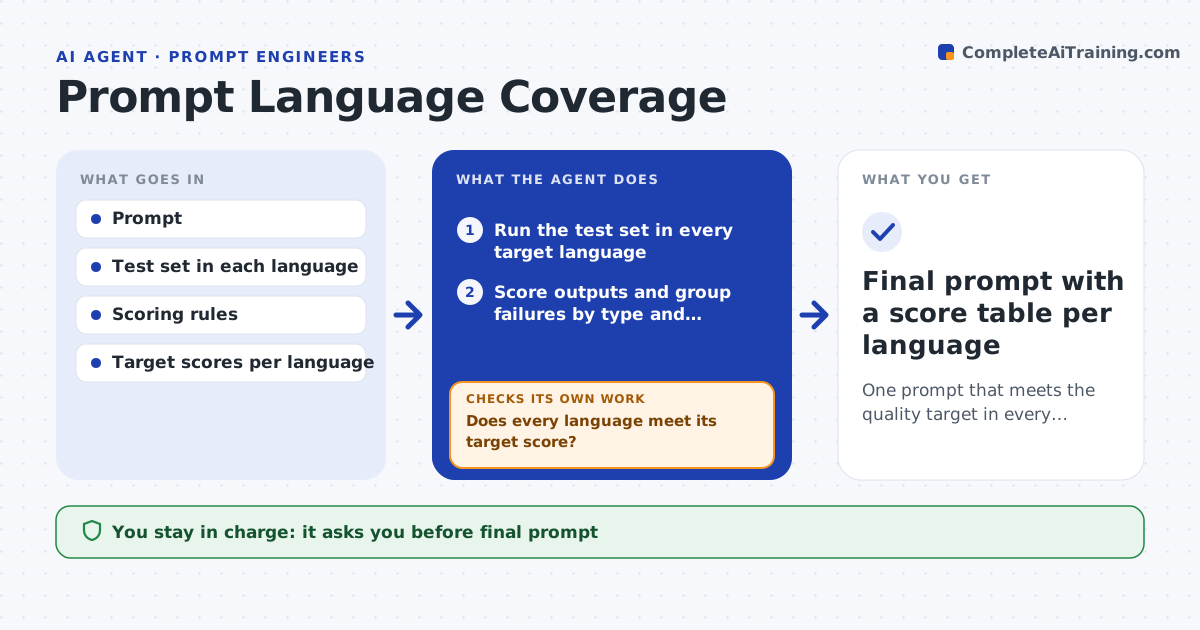
What it does
A prompt tuned in English often slips in other languages. It answers in English, mixes formats, ignores a tone rule or misreads names. This agent takes the English test set and the translated versions for each target language. It runs every language through the prompt, scores each output with the same rules and groups failures by type, for example wrong language, broken format or lost politeness level. For each failing language it drafts a small prompt change and reruns that language. Because a fix for one language can hurt another, it then reruns all languages and compares scores to the earlier round. It loops until every language meets the target. A native reviewer approves the final prompt and a sample of outputs. Edge case: a fix for German formality makes the French output stiff, so the agent narrows the rule.
How it works
Follow the arrows from top to bottom. The orange dashed arrow is the loop: when a check fails, the agent goes back and tries again.
Read the steps as a list
- Prompt changes or a new language is added
- Run the test set in every target language
- Score outputs and group failures by type and language
- Does every language meet its target score?If not: draft a small prompt fix for the failing language and rerun it. Back to step 2.
- Rerun all languages with the new prompt
- Did any other language drop below its earlier score?If not: narrow the fix so it applies only to the failing language. Back to step 4.
- Compare final scores with the first run and list remaining gaps
- Native reviewers approve the prompt and a sample of outputsThe agent waits here for your OK.
- Final prompt with a score table per language
How it decides
A change is kept only if the language it targets improves and no other language drops below its target.
- Fix wrong-language answers before style issues
- Keep a change only if no other language drops more than 2 points
- Escalate a language after three failed fix rounds
- Use native reviewers for any language scoring under target
Make it yours
Every agent is a starting point. You choose these settings for your own situation.
- Target score per language (default 85)
- Languages in scope
- Maximum allowed drop elsewhere (default 2)
- Number of fix rounds before escalation
What keeps you in control
It always asks you first
- Final prompt
- Each language's sample outputs
Hard limits
- Never ships a prompt change without the full rerun
- Never judges quality in a language the reviewer has not signed off
It stops when
- Done: all languages meet target and reviewers approve
- Stop: translated test sets are missing or unreviewed
Set it up
We guide you through the set-up, step by step
Members get the full set-up guide for this agent. No technical skills needed: you copy, paste and upload.
- One set of instructions to paste into your AI, with the clicks for ChatGPT, Claude, Microsoft 365 Copilot, Gemini and Grok
- The agent then walks you through connecting your own data, one source at a time
- A downloadable copy with the flow chart, the rules and the full guide