AI tool
Gemini 3.1 Flash-Lite
Gemini 3.1 Flash-Lite: Google's fastest, lowest-cost Gemini 3 for high-volume execution - sub-second p95 for structured tasks, multimodal tool-calling, ~99.6% success under load and major cost savings.
About Gemini 3.1 Flash-Lite
Gemini 3.1 Flash-Lite is a lightweight inference model exposed via API for high-volume AI pipelines. It focuses on tasks such as tool calling, classification, translation and multimodal (text + image) processing with low latency and cost in mind.
Review
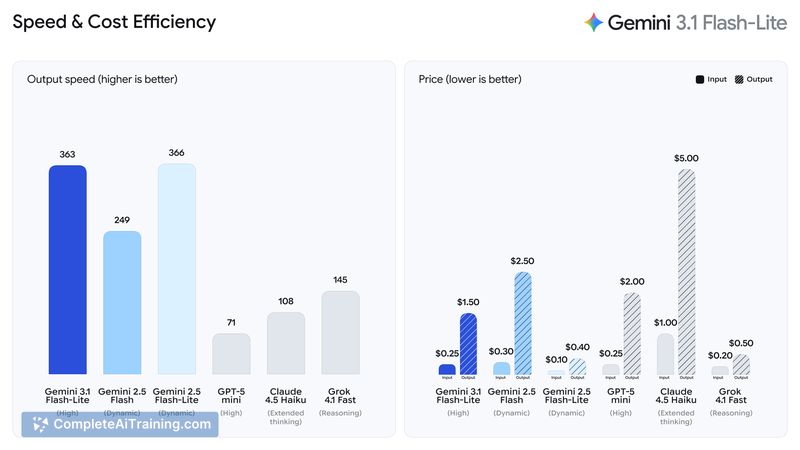
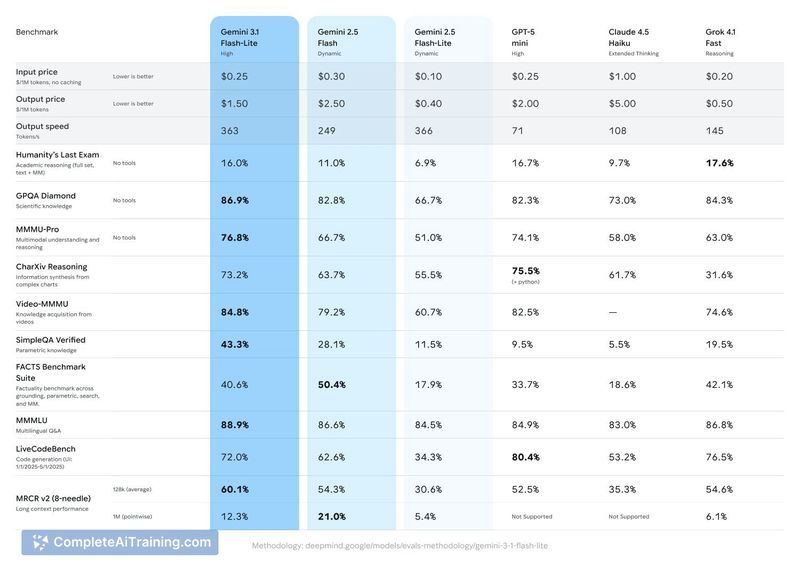
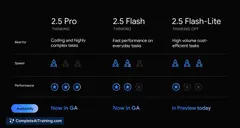
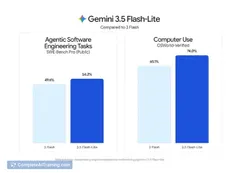
This model targets production use cases where throughput and response time matter more than deep, multi-step reasoning. Performance figures advertised include sub-second p95 latency for structured tasks, roughly 1.8s p95 for full responses, and high success rates under heavy concurrent load, making it a practical choice for agent orchestration and operational AI workloads.
Key Features
- Tool calling and agent orchestration support via API
- Multimodal inputs (text and image) for classification and routing tasks
- Low-latency performance (sub-second p95 for structured tasks; ~1.8s p95 for full responses)
- High concurrency reliability (reported ~99.6% success under heavy load)
- Lower inference cost compared with larger reasoning-focused models
Pricing and Value
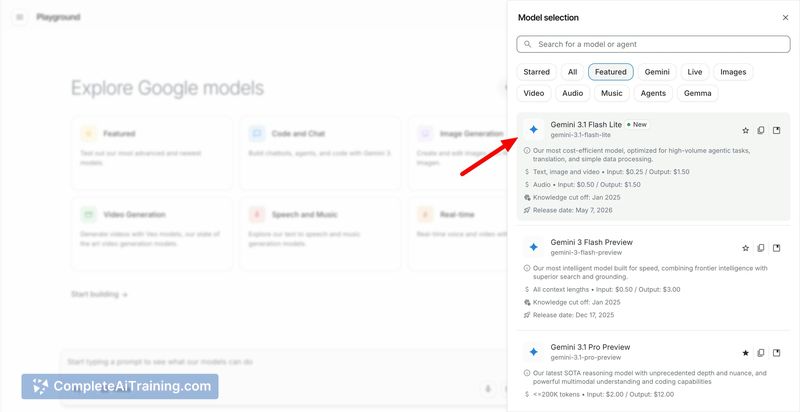
Pricing follows typical API usage models with free options available for experimentation and pay-as-you-go or enterprise plans for production. The value proposition is strongest for organizations that run large volumes of simple to medium-complexity tasks where inference cost and latency dominate operational budgets; some early adopters report substantial cost reductions versus heavier-weight models. Teams should benchmark real workloads to confirm cost and latency benefits for their specific pipelines.
Pros
- Optimized for high-throughput, latency-sensitive production pipelines
- Supports tool calls and orchestration flows, useful for agent-based systems
- Multimodal handling (text + images) increases flexibility for routing and classification
- Lower inference cost can materially reduce operating expenses for large-scale deployments
Cons
- Reduced capability for deep, multi-step reasoning compared with larger models
- Newly launched, so ecosystem resources and community examples may be more limited than established alternatives
- May require integration work to ensure reliability and correctness for edge-case inputs
Overall, Gemini 3.1 Flash-Lite is best suited for AI engineers and teams running high-volume, latency-sensitive agent pipelines that perform classification, routing, translation, moderation or orchestration tasks at scale. For projects that demand complex reasoning, long-form creative generation, or highly specialized understanding, a reasoning-focused model remains a better fit.
Jobs Gemini 3.1 Flash-Lite suits
We checked Gemini 3.1 Flash-Lite against 500+ jobs; these get the most out of it.
Alternatives to Gemini 3.1 Flash-Lite
Other tools that do the same main job. Our AI compared Gemini 3.1 Flash-Lite with similar tools and kept the ones you could use instead.