AI tool
MiniMax M3.1 Flash
MiniMax M3.1 Flash is a fast, low-cost language model for developers building agentic, coding, computer-use, and cybersecurity tasks. It outputs over 200 tokens per second and costs $0.15 per 1M input tokens.
About MiniMax M3.1 Flash
MiniMax M3.1 Flash is a foundation model from MiniMax, positioned as a faster, lower-cost iteration for agentic tasks. The company states it is roughly 3x faster at online inference than its predecessor and 70% cheaper for agentic workloads, with output speeds reaching 200+ tokens per second. It targets coding, computer use, cybersecurity, and general agentic applications.
Review
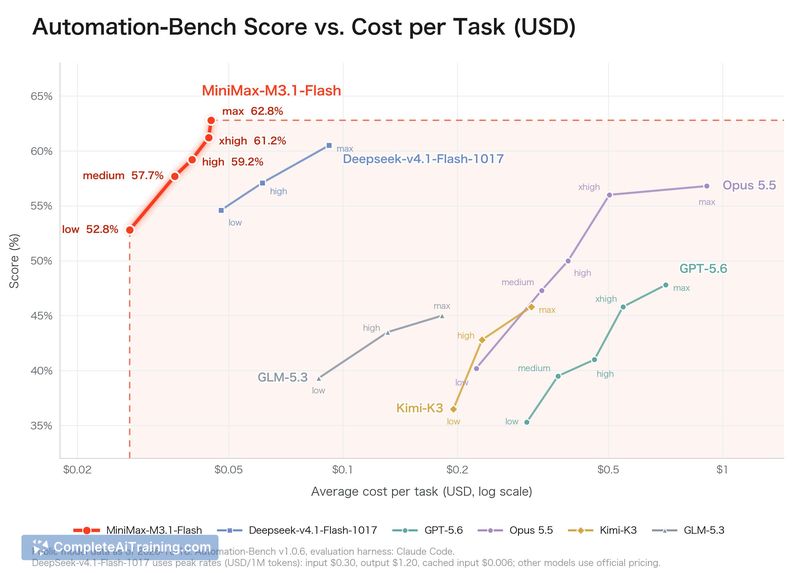
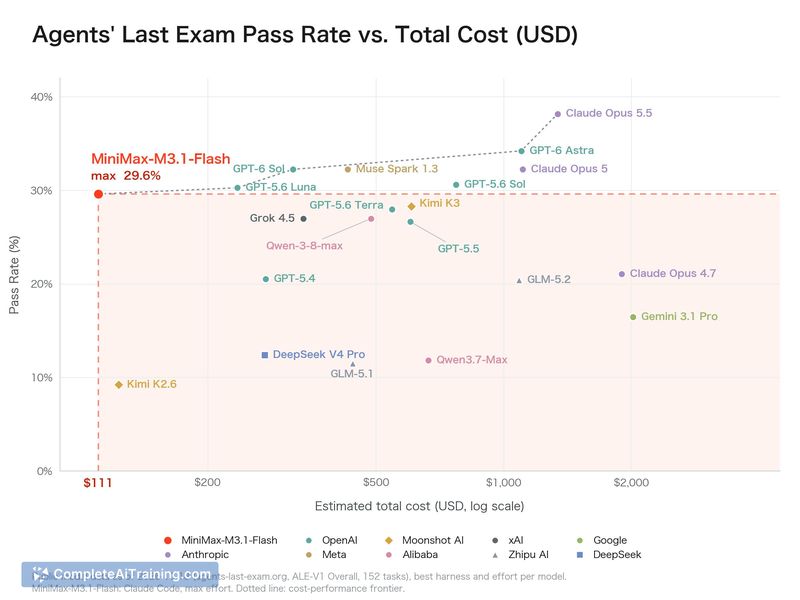
MiniMax M3.1 Flash arrives as a direct update to the company's Flash line, with concrete speed and cost metrics attached. An early version ran anonymously as "Space Bunny" and processed over 200 trillion tokens before this official launch. The model is available now through the MiniMax API, the M Plan subscription, and the MiniMax Code desktop app-weights are promised for later release.
Key Features
- Output at 200+ tokens per second in everyday use, with a median of 170+ tokens per second
- Priced at $0.15 per 1M input tokens, $0.60 per 1M output tokens, and $0.015 per 1M cached input tokens
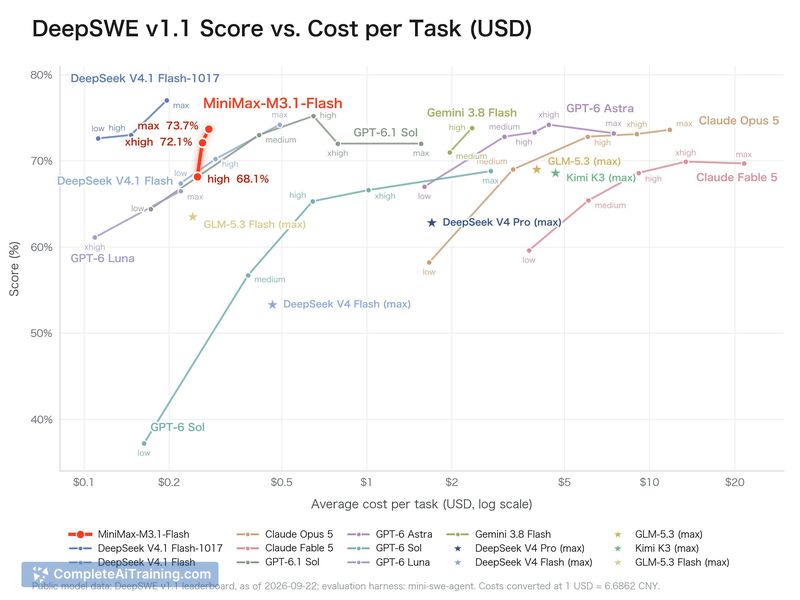
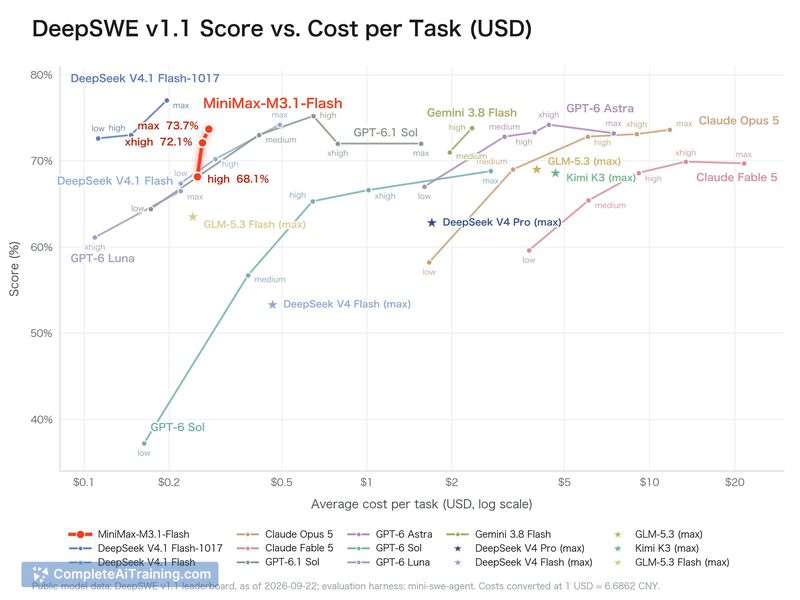
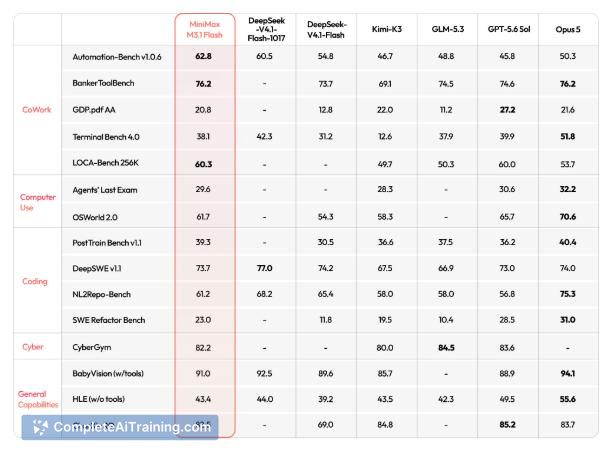
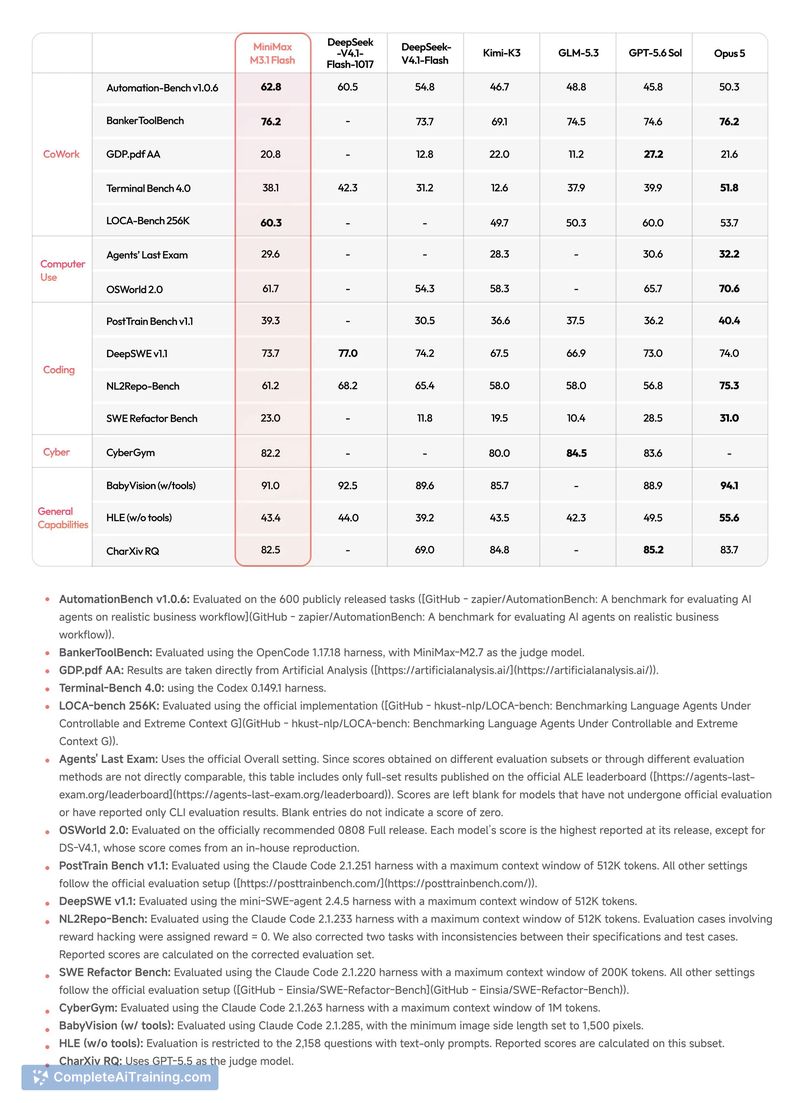
- Benchmarked at 73.7% on DeepSWE v1.1 and 61.7 on OSWorld V2 for agentic and coding tasks
- Scores of 76.2 on BankerToolBench and 82% on CyberGym, as assessed by MiniMax's internal security experts
- Accessible via MiniMax API, M Plan subscription, and MiniMax Code desktop app
Pricing and Value
MiniMax has set flat pricing at $0.15 per 1M input tokens, $0.60 per 1M output tokens, and $0.015 per 1M cached input tokens. The company says this represents a 70% reduction in usage cost for agentic tasks compared to the previous Flash model. The M Plan subscription and MiniMax Code desktop app provide additional access points beyond the API. Weight availability is on the roadmap but not yet delivered.
Pros
- Token pricing is flat and explicitly stated, with a cached input rate that can reduce costs on repeated prompts
- 200+ tokens per second output speed reduces wait time during long agent loops and multi-step tool calls
- Multiple access methods-API, subscription plan, and a desktop app-cover different integration preferences
- Benchmark results on DeepSWE, OSWorld, and CyberGym give reference points for coding and security use
- Processed over 200 trillion tokens during an anonymous pre-launch phase, indicating substantial pre-release testing
Cons
- Weights are not yet available; the model can only be used through MiniMax's hosted services for now
- CyberGym evaluation was conducted by MiniMax's internal security experts, not an external third party
- Not well suited for teams that require on-premise deployment or cannot depend on API-only access without weight files
MiniMax M3.1 Flash fits scenarios where token cost and inference speed directly affect whether an agent workflow is practical-think long-running coding agents or multi-step computer-use tasks. The flat pricing and cached token rate make cost projection straightforward, though the lack of released weights means self-hosted deployment isn't an option at launch. Teams building on the MiniMax API stack will find the speed bump and lower per-token cost immediately applicable.