AI tool
Nimble
Nimble is a web scraping API that collects structured data from online sources. It is designed for developers and data teams who need reliable, large-scale data extraction without managing proxies or parsers.
About Nimble
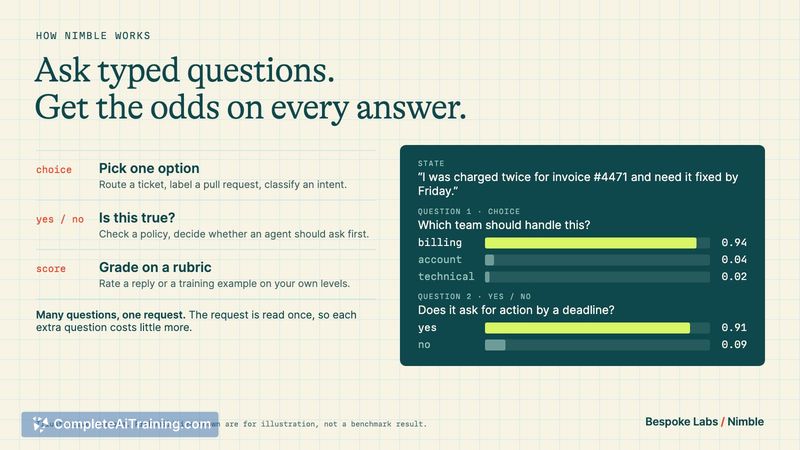
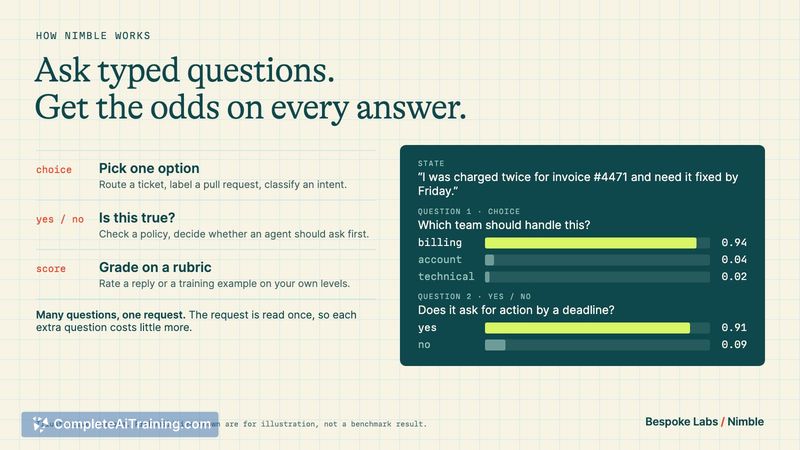
Nimble is a family of decision models built by Bespoke Labs, with the latest versions being Nimble-v4 and Nimble-v4-max. These models focus on making automated decisions and routing unclear cases, and they are accessible through a web console at console.bespokelabs.ai. The project launched shortly after another model called Jev, which the makers cite as a spur for community activity and their own recent modeling advancements.
Review
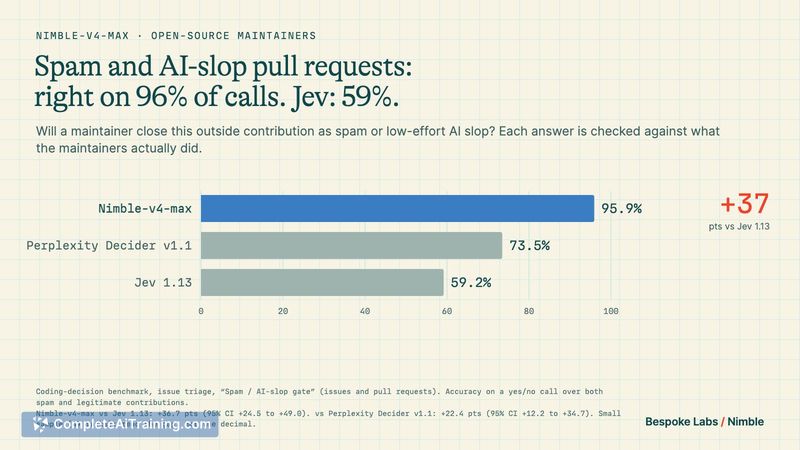
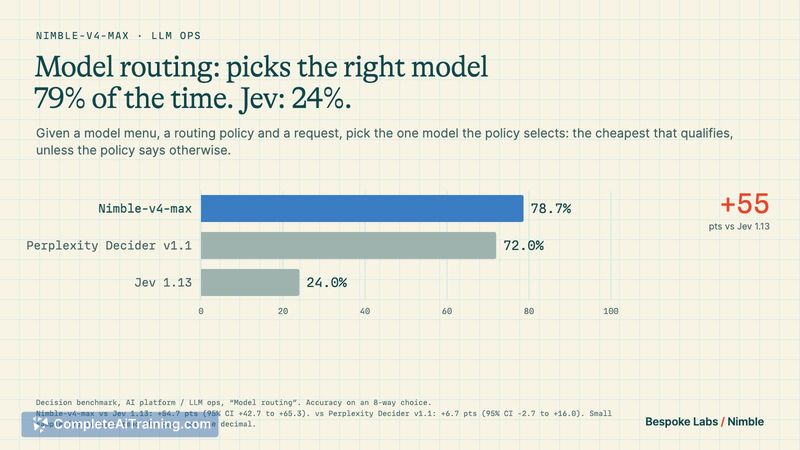
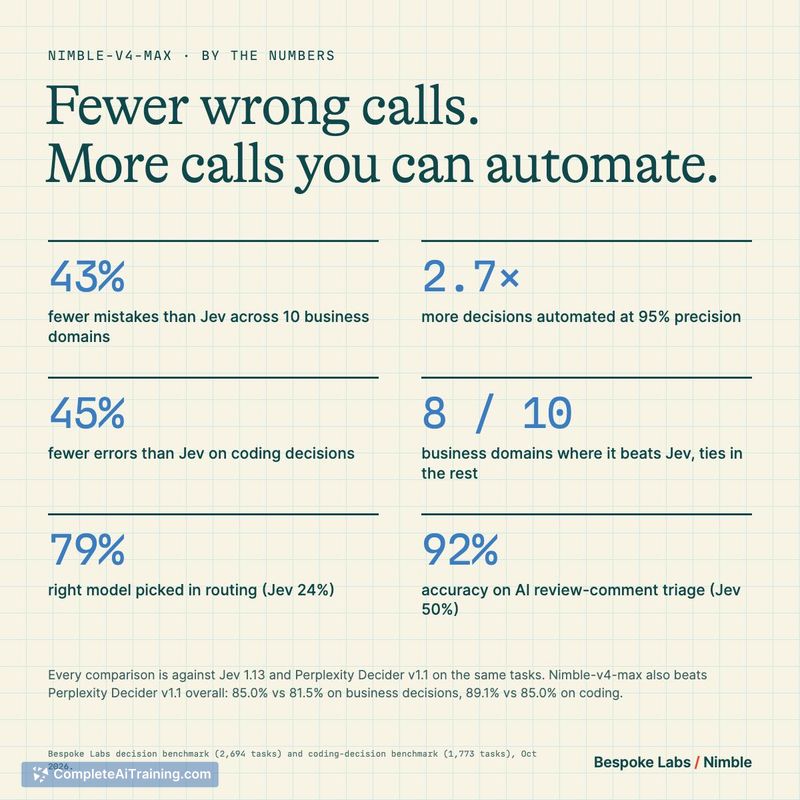
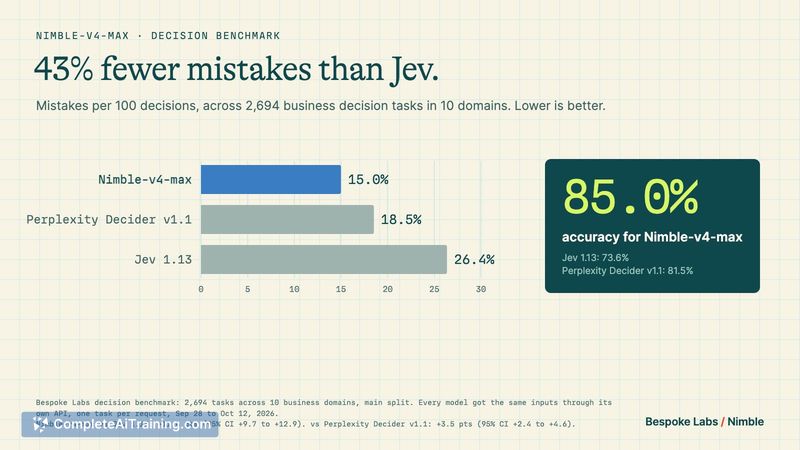
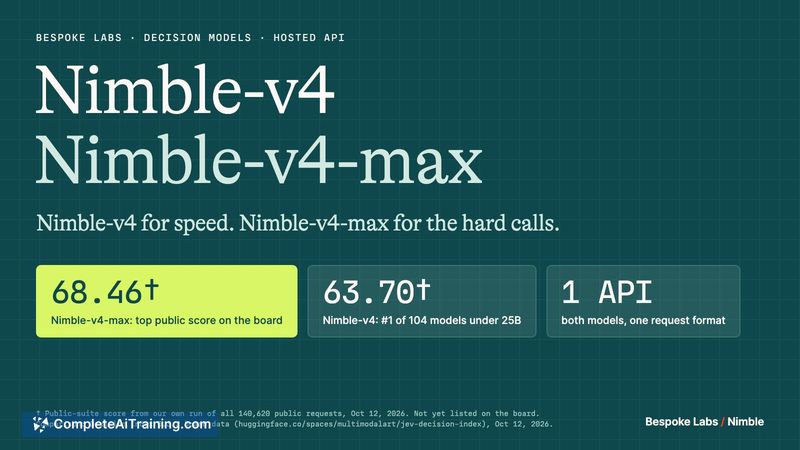
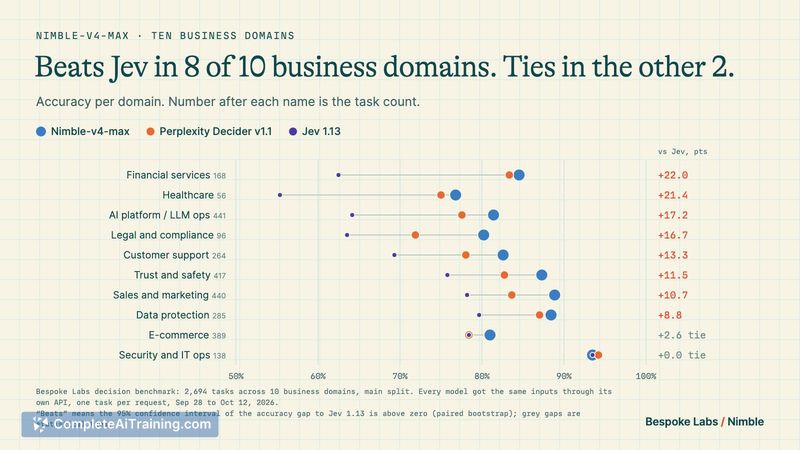
Nimble enters a space where models are judged not just on text generation, but on their ability to choose an action. The v4 release claims strong numbers on the Decision Index public benchmark and on internal evaluations built around real-world tasks. A free tier with credits lets you test it on your own data without an upfront commitment.
Key Features
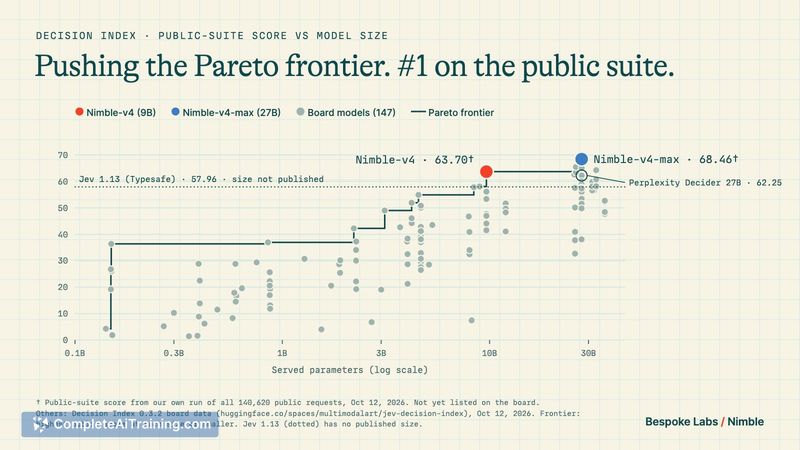
- Ships with two model variants: Nimble-v4 and a larger Nimble-v4-max, with v4-max scoring +10.5 over Jev 1.13 on the Decision Index public benchmark.
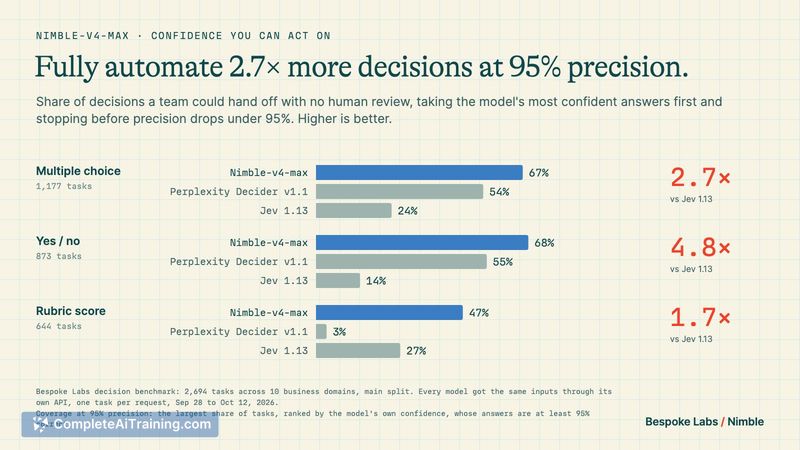
- Returns a confidence score with every decision, so users can set their own cutoff for when a human should step in.
- Supports a "Needs review" label that automatically routes unclear cases for manual inspection.
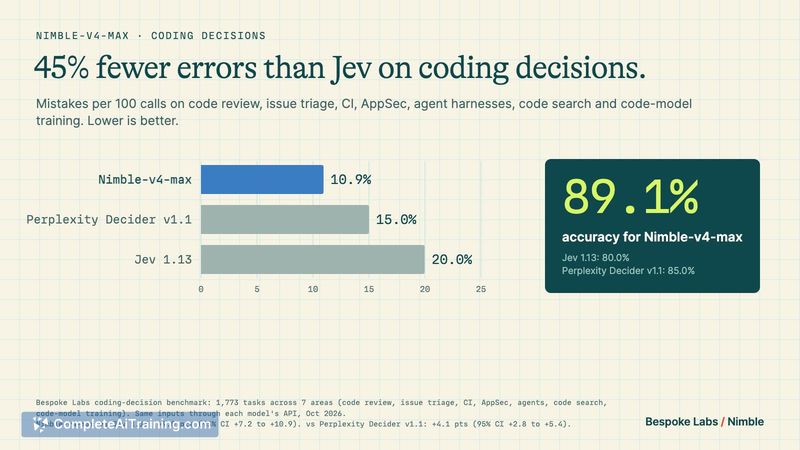
- Internal evaluations report 43% fewer mistakes than Jev and a +50 percentage point improvement on model routing decisions.
- Runs on Google Cloud Run infrastructure, which Bespoke Labs uses for its full stack.
Pricing and Value
The console currently operates with free credits, letting users run their own decisions through the model at no cost. Bespoke Labs has not published a long-term pricing model or detailed rate card. For now, access remains free, but the eventual pricing structure is not yet defined publicly.
Pros
- Benchmark results place Nimble-v4-max at the top of the Decision Index public leaderboard among the referenced models.
- Built-in confidence scoring and a configurable review threshold give teams a straightforward way to manage risk.
- Free credits remove the barrier to testing the model on a team's own decision data.
- Internal evals target practical tasks like model routing, not just abstract benchmarks.
Cons
- Confidence calibration against empirical accuracy is still under development - currently, output probabilities come from softmax scores rather than measured reliability.
- Long-term pricing and rate limits are unannounced, making it hard to plan for production workloads.
- The tool is not well suited for teams that need a fully calibrated, production-hardened decision system today, given the early state of calibration support and the absence of a defined pricing model.
Teams that already run automated decision pipelines and want to benchmark a new model against their own data will find the free console a practical starting point. The configurable review threshold and routing label make it a candidate for workflows where human oversight is still part of the loop. Anyone evaluating it should track the calibration roadmap, since that gap matters for high-stakes automation.