AI tool
ZeroGPU
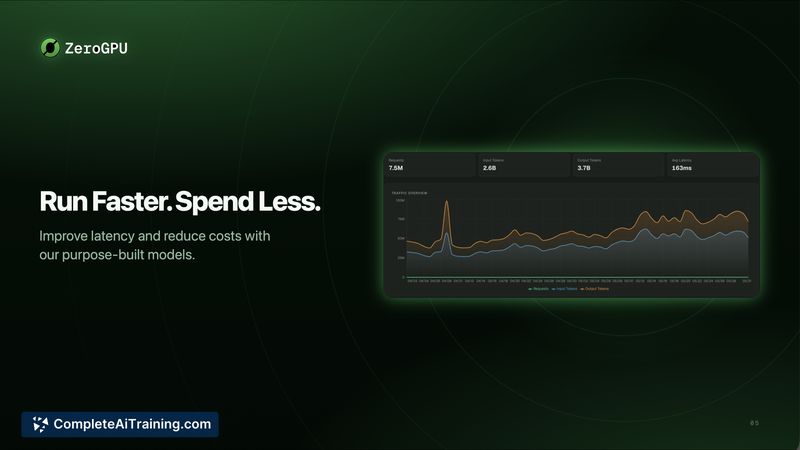
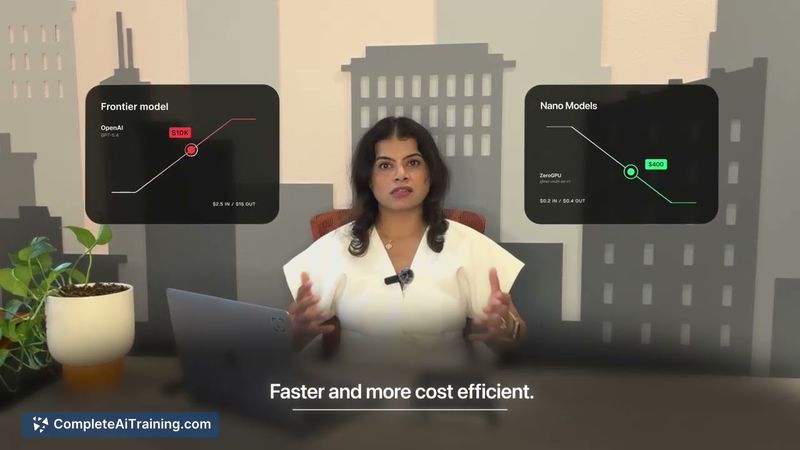
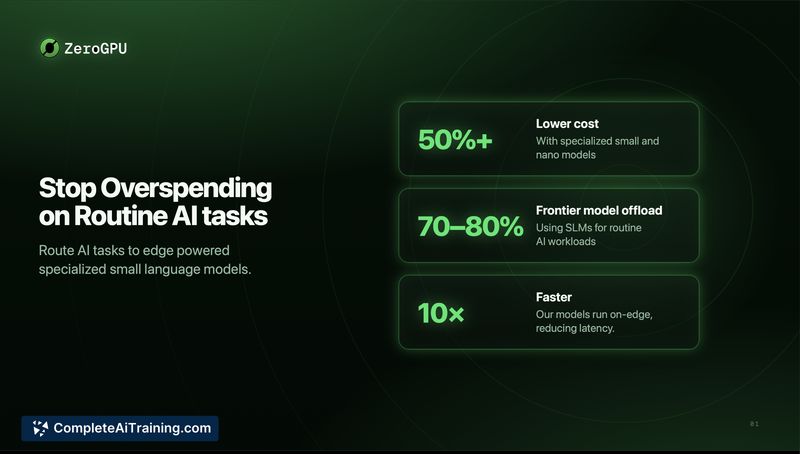
ZeroGPU: a compute-efficiency layer running specialized small LMs on edge for high-volume classification, extraction, moderation and routing-10× lower latency, 50%+ lower cost, 20% higher accuracy.
About ZeroGPU
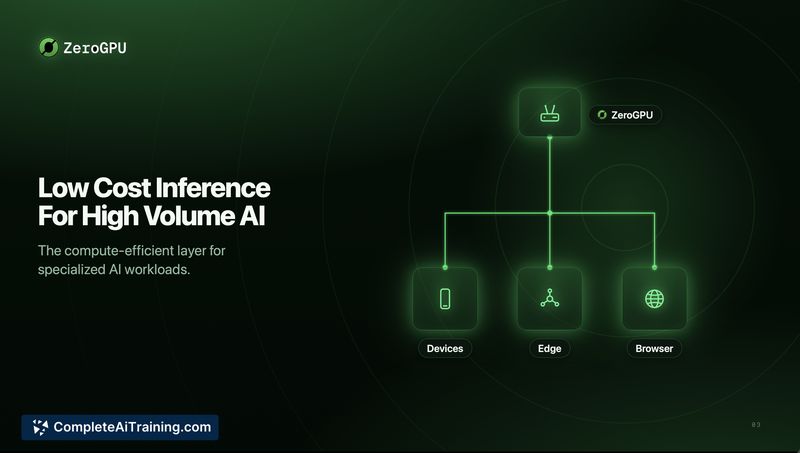
ZeroGPU is a compute-efficient inference layer that runs small, purpose-built language models across an edge-oriented network. It focuses on high-volume, repeatable tasks by reusing existing compute and running models on CPU and edge hosts so fewer calls need expensive large models or GPU provisioning.
Review
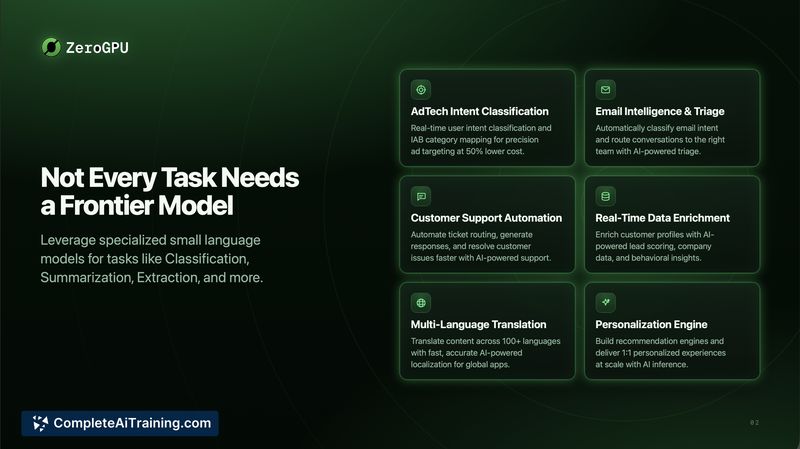
ZeroGPU targets the large slice of application traffic made up of structured, repetitive inference: classification, extraction, moderation, summarization and routing. The platform promises substantial latency and cost improvements for those workloads while providing an OpenAI-compatible API and batch processing for easy integration.
Key Features
- Edge-optimized, CPU-friendly models that run without dedicated GPU provisioning.
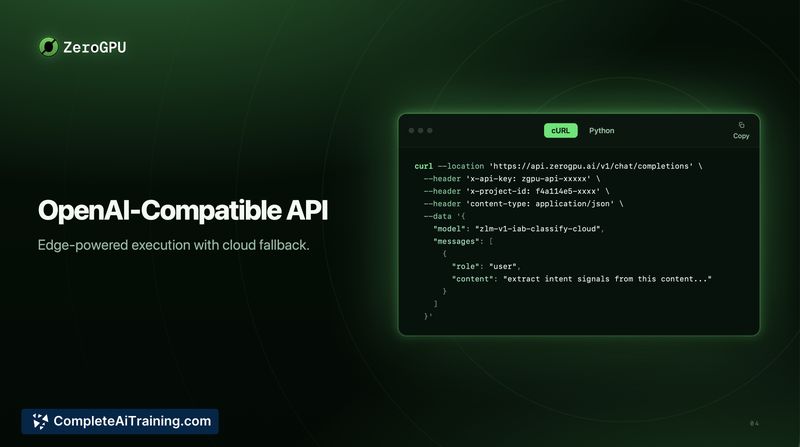
- OpenAI-compatible API endpoints and a Batch API for high-volume jobs.
- Claims of large performance gains on routine tasks (examples include 10× faster latency and 50%+ lower cost compared with using large general-purpose models).
- Support for bringing your own models for production customers and an integration path for task-specific deployments.
Pricing and Value
ZeroGPU offers a free option and an introductory credit to test the platform. Pricing is API-driven and positioned to be materially lower than routing the same traffic through large general-purpose models, with savings coming from CPU-based inference, edge proximity, and batch processing. For teams with heavy, repetitive inference needs, the cost-per-call and associated cloud-efficiency gains make it worth evaluating alongside existing provider bills.
Pros
- Significant latency reductions for high-volume, simple inference tasks.
- Lower per-request cost for routine work compared with sending everything to large models.
- Drop-in API compatibility makes migration straightforward for many applications.
- Batch API and edge deployment options help scale predictable workflows efficiently.
Cons
- Early-stage product; some advanced features (like full self-serve BYO-model flows) are still maturing.
- Not intended for complex reasoning or multi-step problem-solving where large models are required.
- Routing logic and fallback behavior require planning so critical steps still use larger models when appropriate.
ZeroGPU is best for engineering and infrastructure teams that run large volumes of predictable inference-things like classification, extraction, moderation, and summarization-where latency and per-call cost matter. It makes sense as a cost-and-latency optimization layer for apps and agents that already use large models for reasoning but need a cheaper, faster path for routine work.
Jobs ZeroGPU suits
We checked ZeroGPU against 500+ jobs; these get the most out of it.
Alternatives to ZeroGPU
Other tools that do the same main job. Our AI compared ZeroGPU with similar tools and kept the ones you could use instead.