AI app for it and development · no coding needed
AI workflow evaluation service
Evaluation centered on completed customer tasks and consequential failures.
Made for: Businesses deploying customer-facing AI assistants
What it does for you
The problem
Teams lack task-specific evidence of assistant reliability.
What it gives you
Evaluation suite and actionable failure report
What you give it
Representative tasksreference answersacceptance criteria
How it works, step by step
- Define task rubrics
- Create edge cases
- Replay evaluations
- Inspect source use
- Compare versions
- Track regressions
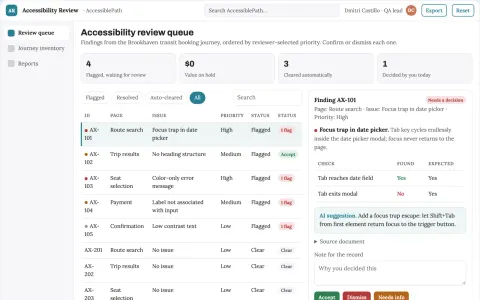
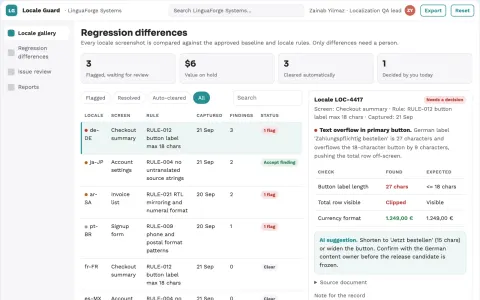
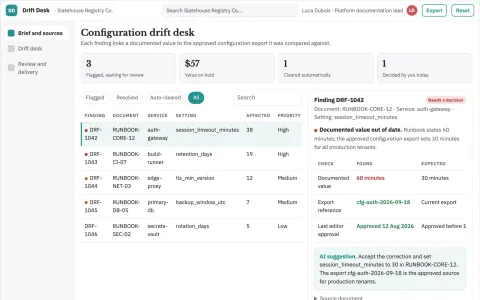
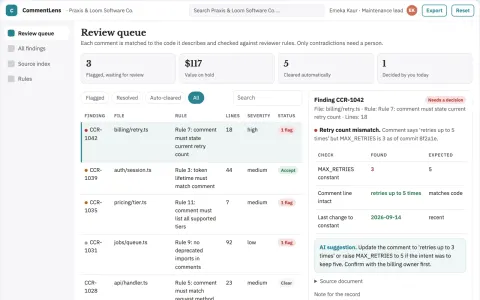
What you see on screen
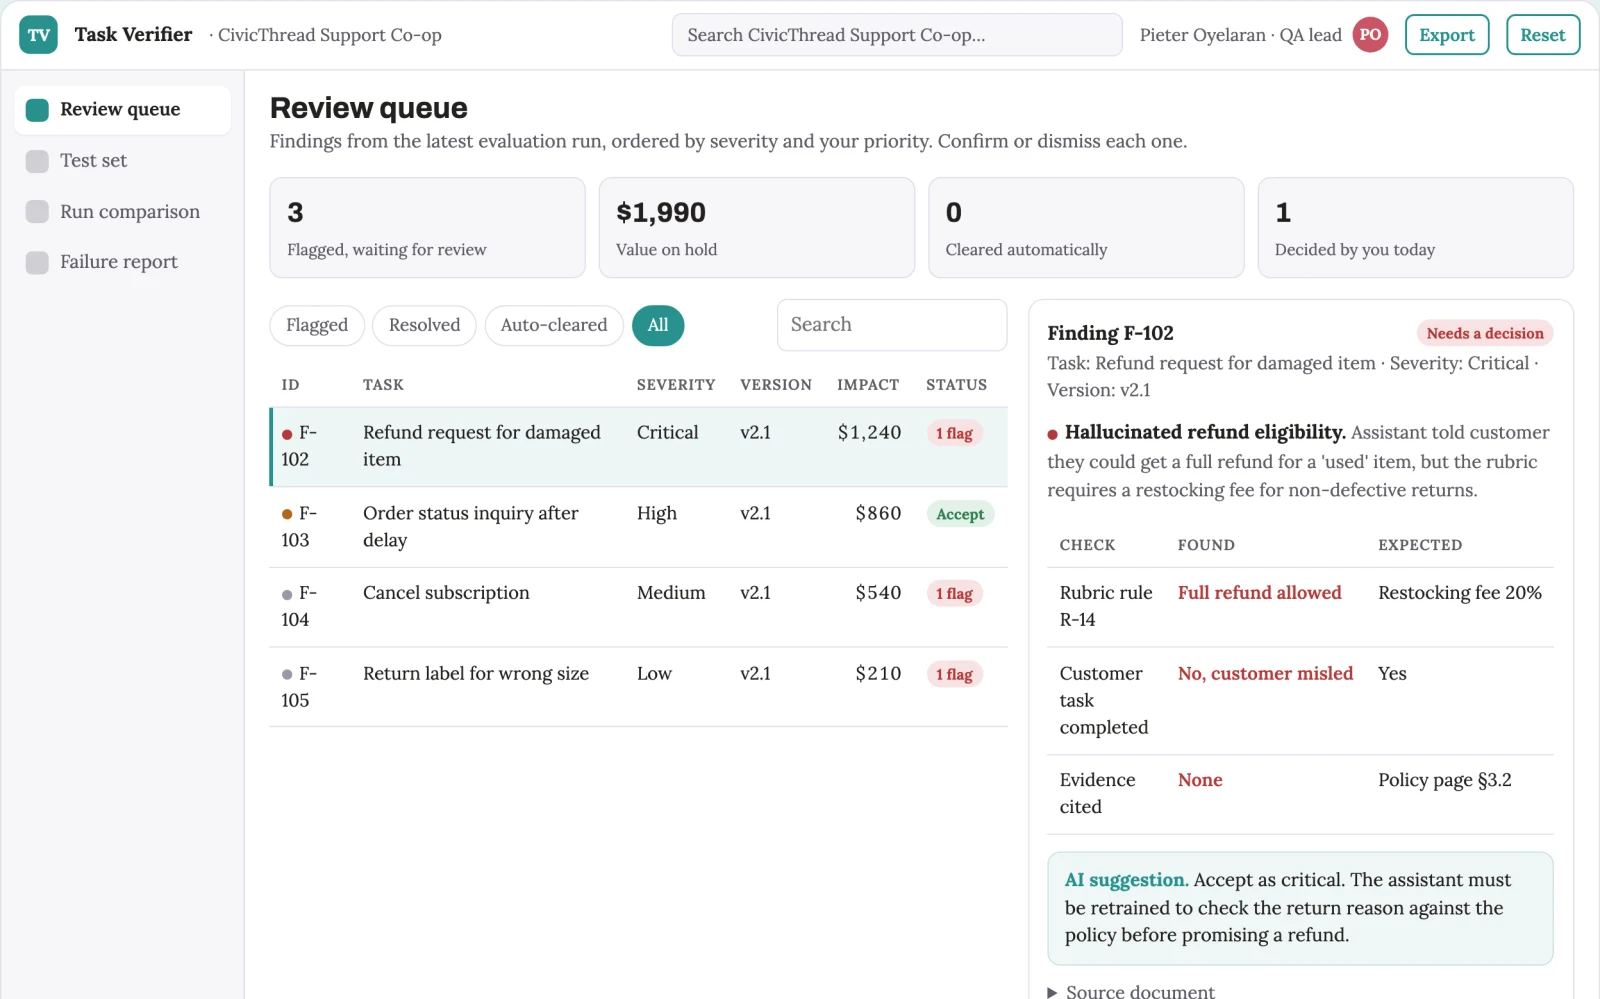
- Test set
- run comparison
- failure evidence
Build it yourself with your AI system
Build this app yourself, no coding needed
Start with a quick version you can try in a few minutes. Like it? Then build the full app by copying and pasting our step-by-step instructions: everything is prepared for you.
Sign in to see how to build it yourself
Build a quick version to try, or get the full app pack for AI workflow evaluation service with the step-by-step building instructions. You don't need any technical skills: you copy, paste and answer a few questions. Both are included in the membership.
4 Have it built for you days to a few weeks
Rather not do it yourself, or want it fully tailored to your data, your way of working and your brand? Nexibeo builds AI workflow evaluation service with you.
What's in the app pack
Included in the Complete AI Training membership.
- The building instructions your AI follows, step by step
- The questions your AI will ask you about your business before it starts
- A clickable demo you can open in your browser, to see how it should work
- A detailed blueprint of the screens, the information it keeps and the checks it runs
Become a member to get the app packAlready a member? Sign in
The files, for the technically curious
- START-HERE.mdHow to build it with your own AI (read first)3 KB
- README.mdOverview and links1 KB
- questions.mdQuestions to answer before you build2 KB
- prompt-cloudflare.mdThe full build prompt, hosted on Cloudflare20 KB
- prompt-vps.mdThe same build on your own server (Docker)20 KB
- spec.jsonData model, API, AI pipeline, acceptance criteria10 KB
- demo/index.htmlThe working demo on sample data195 KB
Questions
Do I need to know how to code?
No. You copy and paste the prompts on this page into ChatGPT or Claude, and the AI does the building. When it asks you something, you answer in your own words.
What does it cost?
The quick version, the app pack and the step-by-step instructions are for members: you pay the membership price, not a price per app (see the plans). Building the full app uses your own ChatGPT or Claude subscription. Putting it online is often cheap or no cost at the start, and your AI tells you before anything costs money.
How long does it take?
The quick version: about two minutes. The real app: an afternoon for a first version you can use, longer if you want every feature.
Can I change it to fit my business?
Yes. Tell your AI what to change in plain words, like “add a column for the price” or “use our logo and colours”. Or have Nexibeo build and customise it for you.
More detailsHow the AI works, safeguards and what to build first
For businesses deploying customer-facing AI assistants, turn representative tasks, reference answers and acceptance criteria into evaluation suite and actionable failure report. Address the recurring problem: teams lack task-specific evidence of assistant reliability. The pilot measures accepted task success and regression detection against the buyer's current method, before the larger build.
Agree review criteria, ingest a sample, generate candidate findings, inspect supporting evidence, let reviewers confirm or dismiss each item, assign corrections, and recheck the affected material. Start with representative tasks, reference answers and acceptance criteria and finish with evaluation suite and actionable failure report.
How the AI works
Propose possible inconsistencies, omissions and rubric matches. Combine extraction with deterministic checks where rules are explicit. Reviewers make the final judgment. Keep false positives and missed cases visible during evaluation.
Safeguards
Protect secrets, customer data and source code. Use controlled environments, technical review and a recoverable deployment process. Validate source access and reviewer availability during the pilot. Maintain customer-level access, data deletion controls and a record of final approvals.
What to build first
Begin with businesses deploying customer-facing AI assistants and one recurring use case. Build the first two modules: define task rubrics; create edge cases. Provide operator assistance for the third module: replay evaluations. Deliver evaluation suite and actionable failure report through a manual review queue. Perform other necessary full-scope functions manually during the pilot. Include all applicable access, accuracy and professional-review controls from the start.
What it can connect to
Authorized repositories, technical documentation, application APIs and logs. Source repositories, task trackers and report exports. Keep findings as review proposals until authorized owners accept the resulting actions. These are candidate integration categories, not verified supported connectors.
The screens in detail
Open on a review queue ordered by reviewer-selected priorities. Show each finding beside the original evidence and applicable rule. Provide accept, dismiss and needs-information controls with reasons. A separate report view summarizes confirmed findings and unresolved items, not raw AI flags. In this product, the first view is test set, followed by run comparison and failure evidence.