AI agent for meteorologists
Model Run Case Selection and Comparison Agent
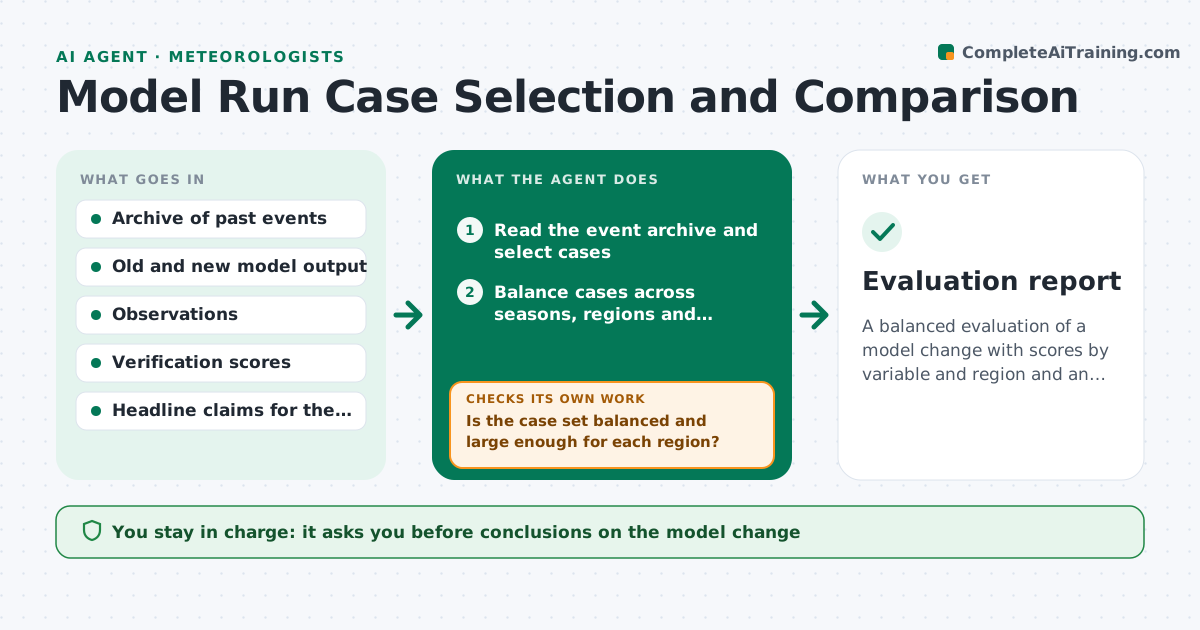
A balanced evaluation of a model change with scores by variable and region and an honest statement of confidence
What it does
Model changes are often judged on a few memorable cases, which can hide a worse result elsewhere. This agent picks a balanced set of past events across seasons, regions and weather types, runs or collects both model versions for each, and scores them against observations by variable and region. It compares the overall result to the headline claim. It checks sample size and widens the case set if the difference is too uncertain to call. It flags where results disagree with the headline, for example better precipitation in the east but worse wind in the west. The lead approves conclusions. Edge case: most selected cases are winter storms, so the agent adds summer convection cases.
How it works
Follow the arrows from top to bottom. The orange dashed arrow is the loop: when a check fails, the agent goes back and tries again.
Read the steps as a list
- New model version ready
- Read the event archive and select cases
- Balance cases across seasons, regions and regimes
- Collect or run both model versions for each case
- Score forecasts against observations
- Is the case set balanced and large enough for each region?If not: add cases for the missing regimes and rescore. Back to step 3.
- Compare scores by variable and region
- Are differences larger than random variation across cases?If not: add cases or mark the result as inconclusive. Back to step 3.
- Compare findings to the headline claims and flag disagreements
- Lead approves conclusionsThe agent waits here for your OK.
- Evaluation report
How it decides
Cases must cover the main regimes. A difference counts only if it exceeds what random variation across cases would give.
- Require at least 30 cases per major regime
- Treat small score differences as inconclusive
- Report variables where the new version is worse
- Use the same observations for both versions
Make it yours
Every agent is a starting point. You choose these settings for your own situation.
- Regimes and regions
- Minimum cases per regime
- Scores used
- Significance rule
What keeps you in control
It always asks you first
- Conclusions on the model change
Hard limits
- Never publishes results as final
- Never drops cases because they look bad
It stops when
- Done: conclusion supported or marked inconclusive
- Stop: model output for the cases is unavailable
Set it up
We guide you through the set-up, step by step
Members get the full set-up guide for this agent. No technical skills needed: you copy, paste and upload.
- One set of instructions to paste into your AI, with the clicks for ChatGPT, Claude, Microsoft 365 Copilot, Gemini and Grok
- The agent then walks you through connecting your own data, one source at a time
- A downloadable copy with the flow chart, the rules and the full guide