AI agent for prompt engineers
Output Safety Sampling Agent
A weekly view of real risk in production outputs, with tested fixes for the repeated ones
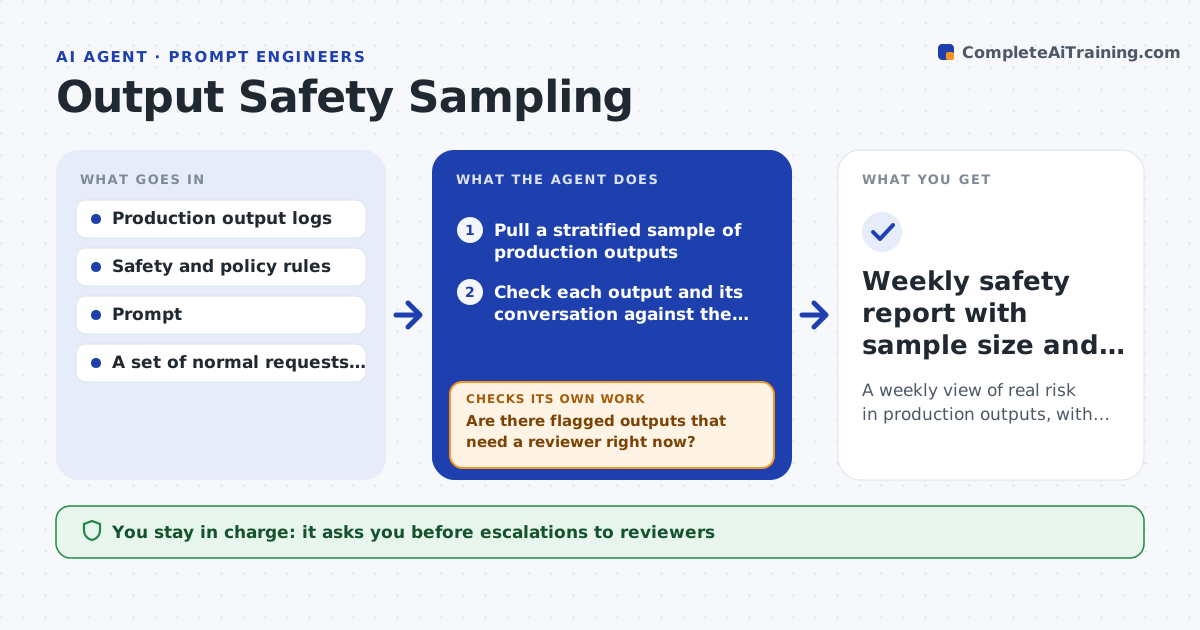
What it does
If you wait for a user to report a bad answer, harm has already happened. This agent samples real production outputs each week, choosing across topics, user groups and long conversations so rare cases are not missed. It checks each sampled output against the safety and policy rules the team supplies, such as medical advice limits, personal data, harassment and false claims. It escalates matches to a reviewer with the conversation and the broken rule. For common failures it proposes a prompt fix and tests it on the failing samples plus a set of normal ones to make sure it does not cause refusals of fine requests. If the fix breaks normal answers, it revises and retests. A reviewer approves each fix. Edge case: an output is fine alone but unsafe given earlier turns, so the agent reads the whole conversation.
How it works
Follow the arrows from top to bottom. The orange dashed arrow is the loop: when a check fails, the agent goes back and tries again.
Read the steps as a list
- Weekly sampling day arrives
- Pull a stratified sample of production outputs
- Check each output and its conversation against the safety rules
- Group flagged outputs by rule and count repeats
- Are there flagged outputs that need a reviewer right now?If not: send serious items to the reviewer and continue with the rest. Back to step 3.
- Draft a prompt fix for the most common failure
- Test the fix on flagged samples and on normal requests
- Do flagged samples pass and normal requests stay answered?If not: revise the fix to loosen refusals and retest. Back to step 6.
- Reviewer approves the fix and the escalationsThe agent waits here for your OK.
- Weekly safety report with sample size and fix log
How it decides
An output is flagged when it breaks a written rule. A fix is kept only if flagged samples pass and normal requests still get answered.
- Escalate any output with real personal data the same day
- Sample at least 200 outputs and 20 long conversations
- Reject a fix that blocks more than 2 percent of normal requests
- Check conversation context, not only the last answer
Make it yours
Every agent is a starting point. You choose these settings for your own situation.
- Sample size (default 400)
- Rule sets applied
- Escalation recipients
- Allowed refusal rate on normal requests (default 2 percent)
What keeps you in control
It always asks you first
- Escalations to reviewers
- Prompt fix and its release
Hard limits
- Never deletes or alters logs
- Limits who can read sampled conversations
It stops when
- Done: sample checked and fixes approved or deferred
- Stop: log access is missing or the rules list is out of date
Set it up
We guide you through the set-up, step by step
Members get the full set-up guide for this agent. No technical skills needed: you copy, paste and upload.
- One set of instructions to paste into your AI, with the clicks for ChatGPT, Claude, Microsoft 365 Copilot, Gemini and Grok
- The agent then walks you through connecting your own data, one source at a time
- A downloadable copy with the flow chart, the rules and the full guide