About Koreshield
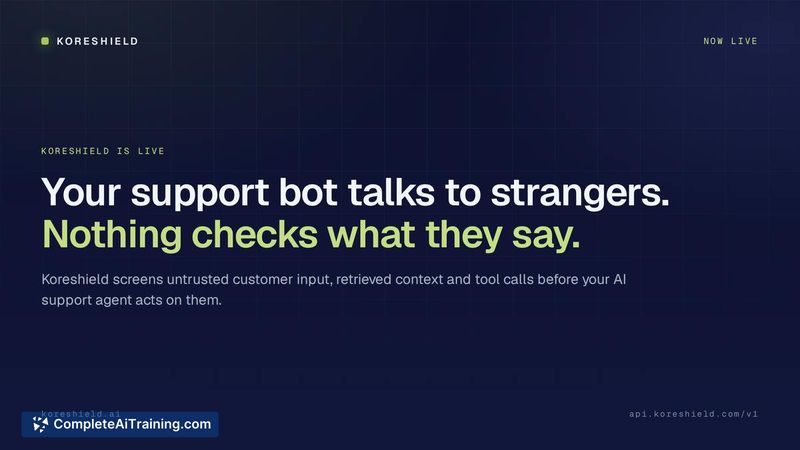
Koreshield is a security layer that sits between an AI support agent and the LLMs it calls. It screens customer messages, retrieved documents, and proposed tool calls before they influence model behavior or trigger application actions. The tool logs every request and block decision, creating an evidence trail for agent activity.
Review
AI support agents operate on inputs they cannot inherently trust-messages from strangers, help articles that might contain hidden instructions, and tool calls the model generates. Koreshield checks all three input streams at the request layer, applying a declarative policy before the model acts. The makers are upfront that response-layer inspection is still on the roadmap, not yet available.
Key Features
- AI Security Gateway: A single API call to
https://api.koreshield.com/v1/scanscreens input before it reaches the model. One policy governs requests across OpenAI, Anthropic, Gemini, and OpenAI-compatible models, with provider-specific streaming and tool call normalization handled internally. - Tool Action Governance: Every tool call the agent proposes is checked against policy before execution. Actions like account edits, order changes, or refunds above a set limit are blocked if they violate the rules.
- RAG Security: The knowledge base the agent retrieves from gets scanned. Hidden instructions embedded in help articles are caught before they become part of the model's context.
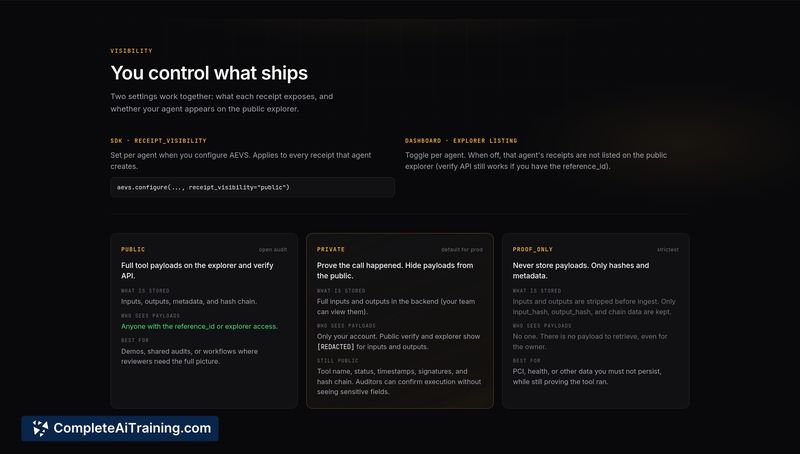
- Decision Logging: Each request and each block is recorded, providing a record of what the agent was allowed to do, what was blocked, and why.
Pricing and Value
The hosted plan includes a one-time 3-day free trial that requires a credit card. Pricing beyond the trial period is not yet defined on the product page. Documentation is available, and an API key can be generated in approximately two minutes.
Pros
- Checks three distinct input channels-user messages, retrieved documents, and tool calls-rather than just the prompt.
- Policy enforcement works across multiple LLM providers without requiring per-provider configuration changes.
- Logs every decision with the evidence attached, so teams can later answer why an action was allowed or blocked.
- Operates at the request layer with a single API call, keeping integration straightforward.
- Includes a detect mode that flags suspicious inputs for review without blocking them, letting teams tune thresholds on their own traffic before enforcing rules.
Cons
- Response-layer inspection is not yet built; the tool only screens inputs, not what the model sends back.
- This tool is not well suited for teams that need full two-way inspection of both prompts and model outputs in a single product today.
- The 3-day trial is short for evaluating false positive rates across a representative sample of real customer interactions, especially for teams with lower traffic volumes.
Koreshield fits teams running AI support agents in production who need request-layer enforcement and an audit trail for tool actions. It's most relevant when the risk of an agent executing an unsafe refund, account change, or policy-violating action outweighs the overhead of adding a screening step before the model. Organizations still building their first prototype or those with minimal tool-calling surface area will find less immediate use here until their agent's action scope expands.
Open 'Koreshield' Website
Your membership also unlocks: