AI tool
MiMo-V2.5 Voice
MiMo-V2.5 Voice - an 8B MIT-licensed ASR for bilingual Chinese-English transcription. High accuracy on dialects, noisy audio, code-switching and lyrics, with prosody-driven punctuation for production-ready transcripts. Available on HuggingFace.
About MiMo-V2.5 Voice
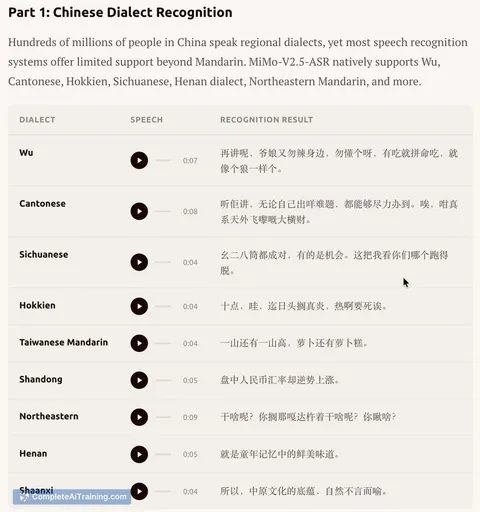
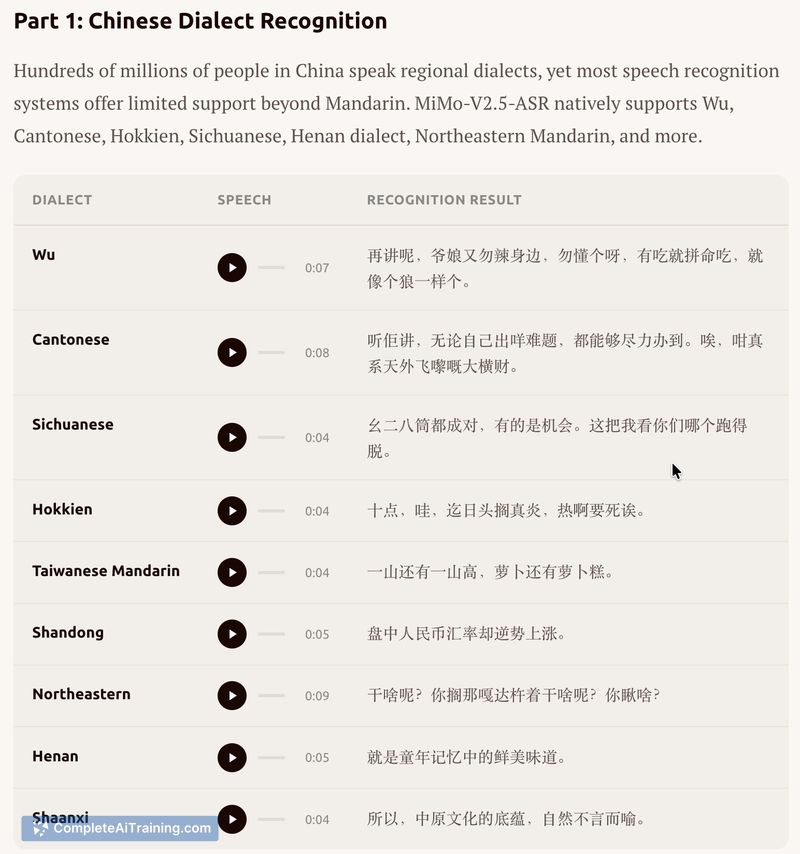
MiMo-V2.5 Voice is an 8B open-source automatic speech recognition (ASR) model focused on bilingual Chinese-English transcription, with explicit support for multiple Chinese dialects, code-switched speech, and song lyrics. It provides a self-hostable option, a Python API, and ready-to-use output with native punctuation to simplify downstream processing.
Review
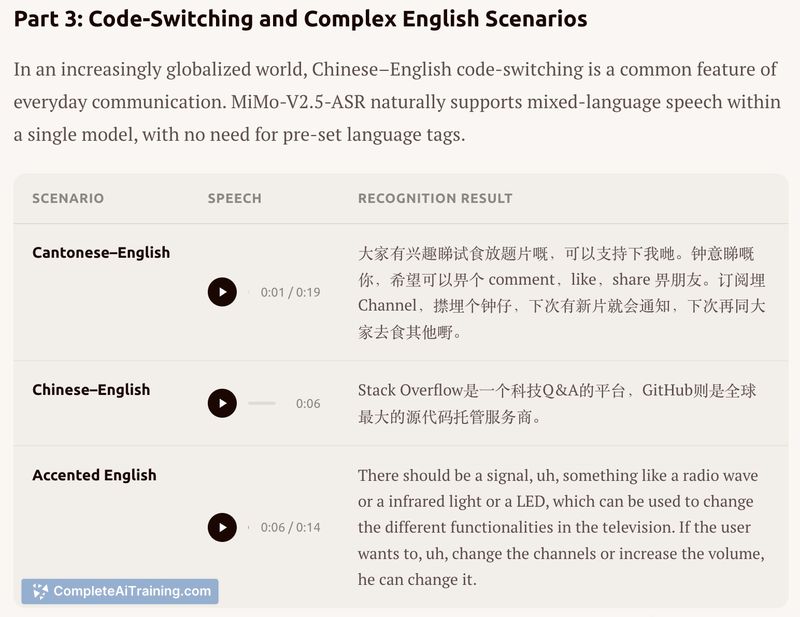
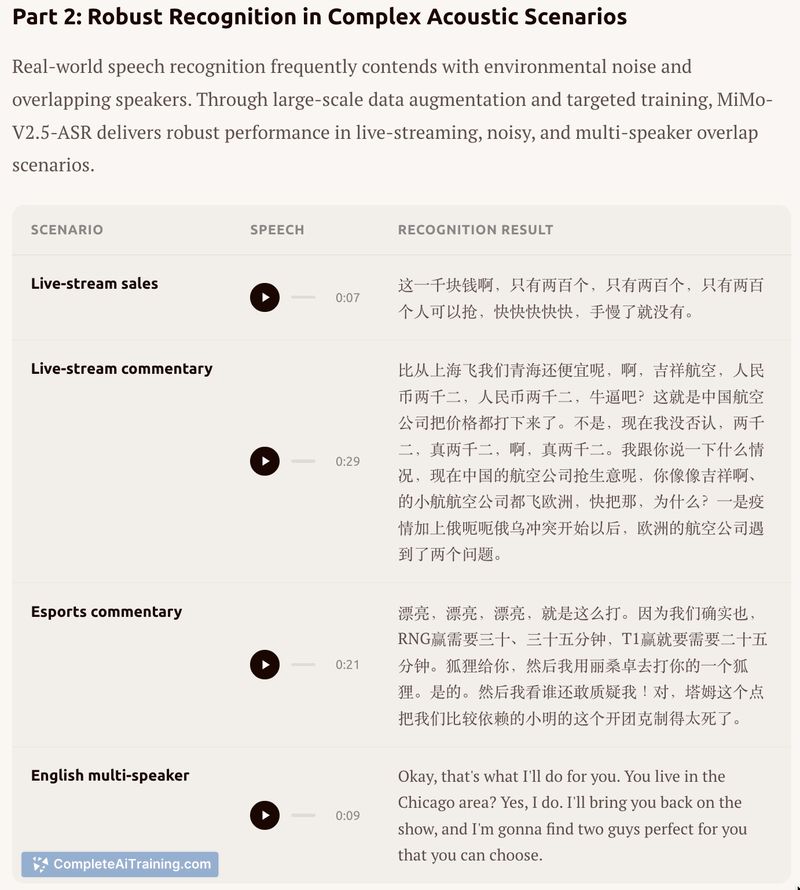
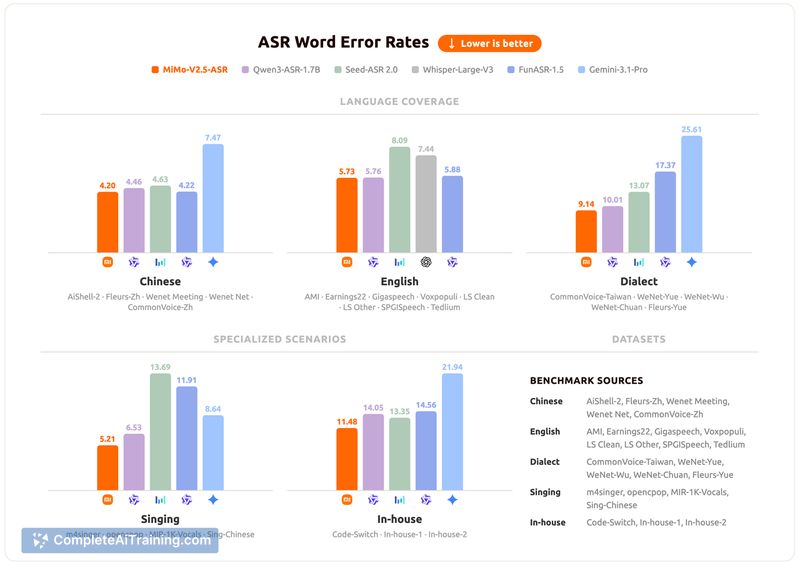
MiMo-V2.5 Voice targets the kinds of audio that commonly break conventional ASR systems: noisy recordings, overlapping speakers, code-switching, and sung vocals. Training and inference choices emphasize practical transcription quality so outputs are more immediately usable in production pipelines.
Key Features
- Bilingual ASR for Chinese and English, with native handling of code-switching.
- Native support for multiple Chinese dialects and lyrics transcription under accompaniment and pitch variation.
- Improved handling of multi-speaker and noisy environments to reduce error rates in non-studio audio.
- Outputs include native punctuation, reducing the need for post-processing steps.
- Open-source MIT license with a Python API, demo interface, and self-hosting capability.
Pricing and Value
MiMo-V2.5 Voice is available under an MIT license and can be used at no direct cost. The self-hostable model eliminates per-call API fees and keeps audio and transcripts on your infrastructure, which can offer significant savings for high-volume or privacy-sensitive deployments. The value proposition centers on reducing the number of separate, domain-specific ASR solutions a team needs to maintain by covering dialects, code-switching, and lyrics in a single model.
Pros
- Strong performance on challenging audio types such as code-switched speech and lyrics, improving real-world utility.
- Native punctuation and cleaner transcripts speed up downstream tasks like search, indexing, and captioning.
- Open-source license and self-hosting options give full control over data and deployment costs.
- One model can replace multiple regional or domain-specific ASR models, simplifying ops and maintenance.
Cons
- At 8B parameters, running the model in low-latency or resource-constrained environments may require substantial compute and engineering effort.
- Production integration, fine-tuning, or customization typically requires experienced ML engineering resources.
- Community-driven support may be more variable compared with paid vendor offerings for enterprise support needs.
MiMo-V2.5 Voice is a strong fit for ML engineers, voice product teams, and developers who need reliable transcription across dialects, code-switched speech, noisy conditions, or music. It works well for services that require self-hosting for privacy or cost reasons, and for projects where reducing post-processing makes pipelines simpler and faster to operate.
Jobs MiMo-V2.5 Voice suits
We checked MiMo-V2.5 Voice against 500+ jobs; these get the most out of it.
Alternatives to MiMo-V2.5 Voice
Other tools that do the same main job. Our AI compared MiMo-V2.5 Voice with similar tools and kept the ones you could use instead.