AI agent for prompt engineers
Output Quality Grading Agent
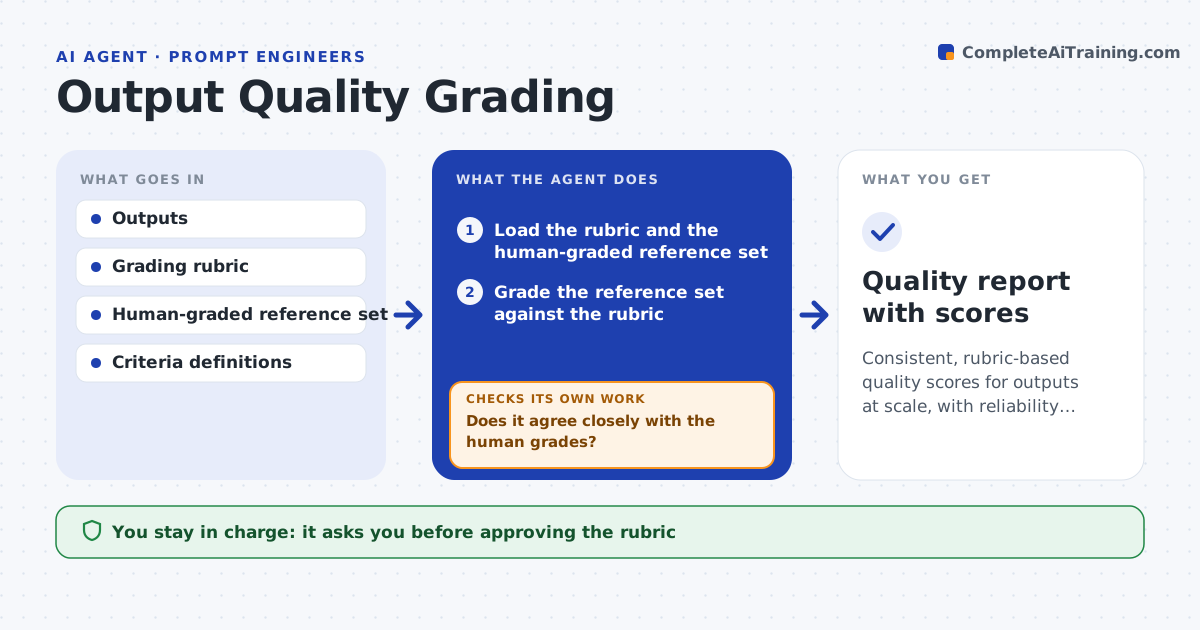
Consistent, rubric-based quality scores for outputs at scale, with reliability checked
What it does
When a prompt runs on hundreds of inputs, grading each output by hand is slow and graders disagree, so quality trends stay unclear. This agent grades a batch of outputs against a written rubric with clear criteria and levels, giving each output a score per criterion and a short reason. To stay reliable, it first grades a set of outputs already graded by a person and measures how often it agrees. If agreement is below your bar, it flags that the rubric or its grading needs tightening before any scores are trusted. Outputs the rubric cannot clearly score go to human review instead of being forced into a level. It summarizes quality across the batch and highlights the weakest criteria. You approve the rubric and review borderline cases.
How it works
Follow the arrows from top to bottom. The orange dashed arrow is the loop: when a check fails, the agent goes back and tries again.
Read the steps as a list
- Batch of outputs ready to grade
- Load the rubric and the human-graded reference set
- Grade the reference set against the rubric
- Does it agree closely with the human grades?If not: flag the rubric criteria that disagree and wait for tightened wording. Back to step 3.
- Grade every output in the batch with a reason per criterion
- Can each output be clearly scored on every criterion?If not: mark the output for human review instead of forcing a level. Back to step 5.
- Summarize quality and highlight weak criteria
- Engineer approves the rubric and reviews borderline casesThe agent waits here for your OK.
- Quality report with scores
How it decides
It scores strictly against the rubric and treats its own grades as trustworthy only when they agree closely with the human reference set.
- Score strictly against the rubric
- Trust scores only when agreement is high
- Send unscoreable outputs to human review
Make it yours
Every agent is a starting point. You choose these settings for your own situation.
- Rubric and criteria
- Agreement bar
- Reference set size
- Report format
What keeps you in control
It always asks you first
- Approving the rubric
- Reviewing borderline cases
Hard limits
- Does not present scores as reliable below the agreement bar
- Routes ambiguity to people
It stops when
- Done: batch graded with reliability shown
- Stop: no rubric or reference set exists
Set it up
We guide you through the set-up, step by step
Members get the full set-up guide for this agent. No technical skills needed: you copy, paste and upload.
- One set of instructions to paste into your AI, with the clicks for ChatGPT, Claude, Microsoft 365 Copilot, Gemini and Grok
- The agent then walks you through connecting your own data, one source at a time
- A downloadable copy with the flow chart, the rules and the full guide