About StillTalk
StillTalk is a browser-based tool that animates a single generated photo into a talking character. The rendering happens live on the user's device-the server transmits only speech and compact movement data, not a video stream. It launched with five characters, supports six languages, and allows visitors to type custom sentences without creating an account.
Review
StillTalk takes a different approach from cloud-rendered avatar services. Instead of streaming video, it sends viseme timing data that a local browser engine uses to draw each frame. The result is a talking photo that runs without per-minute cloud rendering costs, though it also means there's no built-in video export at this stage. The public demo lets anyone test the engine immediately, with prepared lines and a free-text typing option that draws from a shared speech pool.
Key Features
- On-device rendering engine that animates a static photo frame by frame in the browser, using movement data rather than video.
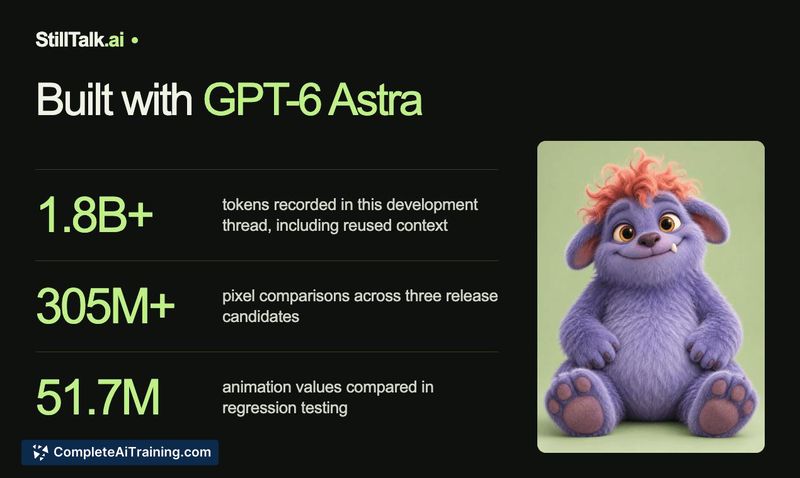
- Five pre-built characters ranging from photorealistic faces to a cartoon creature, with four of them created in a single day using GPT-6 Astra.
- Six supported languages with per-character, per-language lip-sync calibration drawn from a corpus of 980 speech samples.
- Live typing mode that speaks any user-written sentence, subject to free-tier speech pool limits.
- No signup required for the demo; all prepared tongue twisters and character lines remain playable even when the live typing pool is exhausted.
Pricing and Value
The current demo is free with no signup. Live typing draws from a free speech pool that has per-person limits; when that pool runs out, prepared lines continue to work. The maker has mentioned a commercial API and a custom-character beta on the roadmap, but specific pricing for those has not yet been defined.
Pros
- Runs directly in the browser without installing software or creating an account.
- On-device rendering avoids recurring cloud rendering costs tied to video streaming.
- Per-character, per-language calibration means switching a character's language also switches its lip-sync tuning.
- Live typing lets users test spontaneous sentences immediately, which is useful for evaluating speech quality.
- Engine architecture keeps the data payload small-only speech and movement coordinates travel over the network.
Cons
- No video export capability yet; users who want to save or share clips must record their screen separately.
- Live typing depends on a shared free speech pool that can run out, limiting ad-hoc use during high traffic periods.
- StillTalk is not well suited for users who need a finished video file or a full-bodied animated avatar with gestural range-the current characters are head-and-shoulders only, and export is a planned future feature.
StillTalk fits scenarios where a lightweight, embeddable talking character adds value without recurring streaming costs-language-learning apps, website guides, or support agents that speak on demand. It's less relevant for projects that require downloadable video output or full-body animation right now. The public demo gives a clear picture of what the engine handles today, and the roadmap items-API access, custom photo characters, and video export-will determine how broadly it applies beyond its current scope.
Open 'StillTalk' Website
Your membership also unlocks: