AI app for it and development · no coding needed
Multi-model AI request routing control plane
Reduce model spend and manual routing while keeping a single policy across tools.
Made for: Platform and engineering teams running several AI models across internal tools
What it does for you
The problem
Requests are sent to one default model, so cost, latency and quality vary without a central routing policy.
What it gives you
Reviewed routing policy and per-request decision log
What you give it
Provider credentialsrouting rulestask metadatabudget limits
Build your own version of GPT Router, Humiris AI and more
One app with what these 5 AI tools do, yours to keep and change: GPT Router, Humiris AI, Weave Router 2.0, Harness Router, Zerg Router.
Everything these tools do, in one app
- Automatic model routing Automatically selects and sends each request to the most suitable AI model based on the task.Found in GPT Router, Humiris AI, Weave Router 2.0 and 2 more
- Customizable routing rules Lets users define rules or preferences for how requests are routed, such as by query type, context, or cost.Found in GPT Router, Humiris AI, Weave Router 2.0
- Multi-model integration Connects to and routes across multiple AI engines or providers from a single interface.Found in GPT Router, Humiris AI, Weave Router 2.0 and 1 more
- Real-time routing decisions Makes routing decisions on the fly to optimize response speed and relevance.Found in GPT Router
- Monitoring dashboard Provides a dashboard to monitor and manage routing performance and usage.Found in GPT Router
- Model mixing Combines multiple top-tier models to improve accuracy and performance.Found in Humiris AI
- Customizable reasoning Adapts the AI's reasoning processes to meet specific business or technical needs.Found in Humiris AI
- Flexible deployment Offers various hosting solutions to address security and compliance requirements.Found in Humiris AI
- OpenAI ecosystem integration Fully compatible with the OpenAI ecosystem for easy incorporation into existing architectures.Found in Humiris AI, Zerg Router
- Complexity-scored routing Routes requests based on task difficulty using a classifier trained on agentic coding sessions.Found in Weave Router 2.0
- Cache-aware switching Tracks cache state per provider and session, switching models only when savings exceed cache rebuild costs.Found in Weave Router 2.0
- Multi-subscription routing Allows running models from one subscription inside another tool, routing by complexity, cost, or remaining quota.Found in Weave Router 2.0
- Per-turn savings visibility Shows how much quota each request saves on every turn.Found in Weave Router 2.0
- Configurable model pool Lets users select which models the router picks from and set cost-versus-speed preferences.Found in Weave Router 2.0
- Tiered decision paths Uses a fast path for obvious tool calls, Jev for ambiguous cases, and bounded MCTS for complex multi-step decisions.Found in Harness Router
- Codex hook integration Integrates with Codex via SessionStart and PreToolUse hooks to route or re-plan calls transparently before execution.Found in Harness Router, Zerg Router
- MCP exposure Exposes the routing layer through the Model Context Protocol for other MCP-compatible systems to query.Found in Harness Router
- Framework-agnostic design Works as a standalone routing layer without locking users into a specific agent framework.Found in Harness Router
- Open source Provides the full codebase for inspection, modification, and self-hosting.Found in Harness Router
- Scoped API keys Accepts per-tool API keys to keep routing policy centralized in the account.Found in Zerg Router
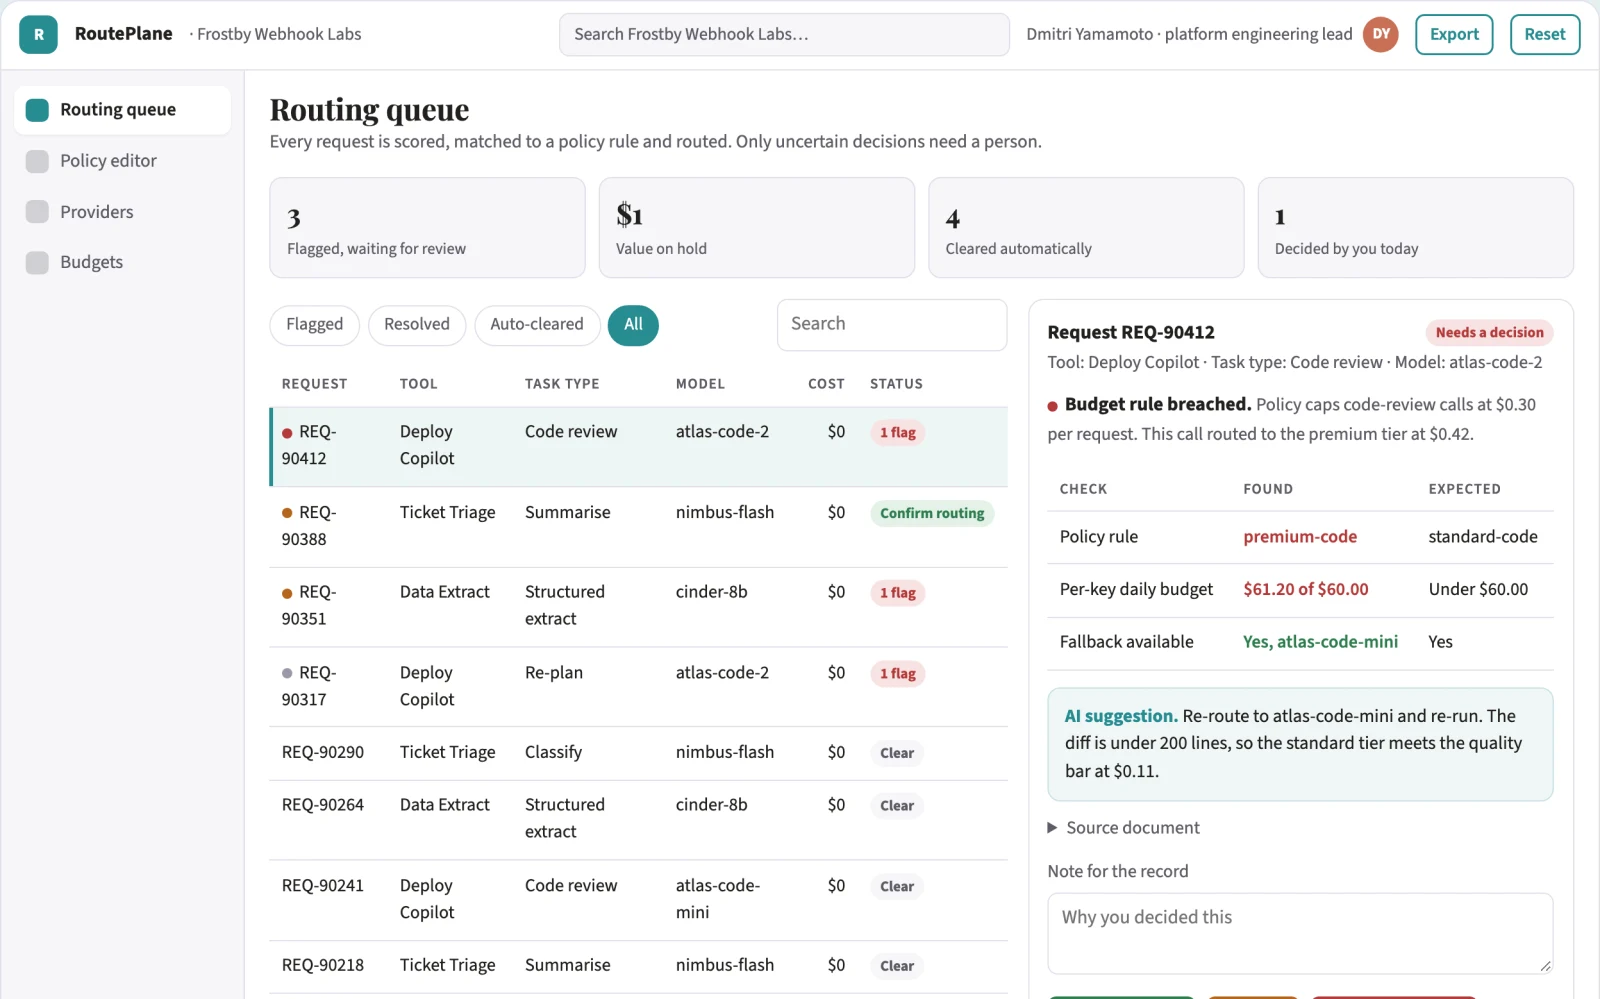
- Per-key daily budgets Enforces daily spending limits at request time, stopping keys when they hit their limit.Found in Zerg Router
- Automatic fallback chains Automatically tries the next model in sequence when a provider returns errors, rate limits, or timeouts.Found in Zerg Router
- Quota visibility Displays remaining weekly quota and reset dates across connected accounts.Found in Zerg Router
- Bring your own keys Allows users to use their own provider credentials instead of the router's paid usage.Found in Zerg Router
How it works, step by step
- Route each request to the most suitable model by task type
- Apply user-defined routing rules by query type, context or cost
- Connect and route across multiple AI providers from one interface
- Decide routing in real time for speed and relevance
- Show a dashboard of routing performance and usage
- Mix several top-tier models to improve accuracy
- Adapt reasoning settings to business or technical needs
- Support flexible hosting for security and compliance
- Stay compatible with the OpenAI ecosystem
- Score task complexity and route by difficulty
- Track cache state per provider and switch only when savings exceed rebuild cost
- Route models from one subscription inside another tool by complexity, cost or quota
- Show per-turn quota savings for each request
- Let users pick the model pool and set cost-versus-speed preference
- Use tiered decision paths for obvious, ambiguous and complex calls
- Integrate with Codex hooks to route or re-plan before execution
- Expose routing through MCP for other compatible systems
- Work as a standalone layer without framework lock-in
- Provide the full codebase for inspection and self-hosting
- Accept per-tool API keys with centralized policy
- Enforce per-key daily budgets at request time
- Fall back automatically on errors, rate limits or timeouts
- Display remaining quota and reset dates across accounts
- Allow bring-your-own provider credentials
Build it yourself with your AI system
Build this app yourself, no coding needed
Start with a quick version you can try in a few minutes. Like it? Then build the full app by copying and pasting our step-by-step instructions: everything is prepared for you.
Sign in to see how to build it yourself
Build a quick version to try, or get the full app pack for Multi-model AI request routing control plane with the step-by-step building instructions. You don't need any technical skills: you copy, paste and answer a few questions. Both are included in the membership.
4 Have it built for you days to a few weeks
Rather not do it yourself, or want it fully tailored to your data, your way of working and your brand? Nexibeo builds Multi-model AI request routing control plane with you.
What's in the app pack
Included in the Complete AI Training membership.
- The building instructions your AI follows, step by step
- The questions your AI will ask you about your business before it starts
- A clickable demo you can open in your browser, to see how it should work
- A detailed blueprint of the screens, the information it keeps and the checks it runs
Become a member to get the app packAlready a member? Sign in
The files, for the technically curious
- START-HERE.mdHow to build it with your own AI (read first)3 KB
- README.mdOverview and links5 KB
- questions.mdQuestions to answer before you build2 KB
- prompt-cloudflare.mdThe full build prompt, hosted on Cloudflare25 KB
- prompt-vps.mdThe same build on your own server (Docker)25 KB
- spec.jsonData model, API, AI pipeline, acceptance criteria12 KB
- demo/index.htmlThe working demo on sample data196 KB
Questions
Do I need to know how to code?
No. You copy and paste the prompts on this page into ChatGPT or Claude, and the AI does the building. When it asks you something, you answer in your own words.
What does it cost?
The quick version, the app pack and the step-by-step instructions are for members: you pay the membership price, not a price per app (see the plans). Building the full app uses your own ChatGPT or Claude subscription. Putting it online is often cheap or no cost at the start, and your AI tells you before anything costs money.
How long does it take?
The quick version: about two minutes. The real app: an afternoon for a first version you can use, longer if you want every feature.
Can I change it to fit my business?
Yes. Tell your AI what to change in plain words, like “add a column for the price” or “use our logo and colours”. Or have Nexibeo build and customise it for you.
More detailsHow the AI works, safeguards and what to build first
Reduce model spend and manual routing while keeping a single policy across tools. For platform and engineering teams running several AI models across internal tools, convert provider credentials, routing rules, task metadata and budget limits into a reviewed routing policy and per-request decision log. The benefit is a testable hypothesis, measured through cost per accepted request and routing decision accuracy; do not assume that AI output alone produces business value.
Confirm the buyer's problem and scope, collect provider credentials, routing rules, task metadata and budget limits, then follow this sequence: 1. Route each request to the most suitable model by task type. 2. Apply user-defined routing rules by query type, context or cost. 3. Connect and route across multiple AI providers from one interface. Resolve uncertain cases with qualified reviewers, approve reviewed routing policy and per-request decision log, and measure cost per accepted request and routing decision accuracy against a documented baseline.
How the AI works
Use AI to interpret permitted inputs, suggest structured mappings and generate candidate outputs for the three stated task modules. Use deterministic code for arithmetic, schema validation, hard constraints and reproducible tests. Review source-linked explanations and uncertainty before accepting results. One fixed provider set and approved hosting region; final policy and budget changes remain human. A model suggestion is never a verified fact, professional decision or authorization to act.
Safeguards
Preserve provider credentials, request privacy, source attribution and usage permissions. Named owners approve policy and budget changes and external routing scope. One fixed provider set and approved hosting region; final policy and budget changes remain human. Keep all consequential actions under authorized human control and do not fabricate missing inputs, permissions, professional judgments or market evidence.
What to build first
Pilot scope: One fixed provider set and approved hosting region; final policy and budget changes remain human. Implement one approved input format, a bounded representative case set and the first two task modules: route each request to the most suitable model by task type; apply user-defined routing rules by query type, context or cost. Support the third module with operator review: connect and route across multiple AI providers from one interface. Include source references, corrections, basic organization access, approval states, export and value measurement. Use managed operator assistance for unresolved exceptions. The cost estimate covers this narrow prototype, not unrestricted multi-tenant scale, complex production integrations, specialist certification or physical operations.
What it can connect to
Customer-owned provider accounts, internal tools and approved model endpoints. Cloud secret storage, CI/CD pipelines and observability destinations. Start with file exchange and validate destination specifications before promising direct publishing. Start with authorized file exchange. Validate current provider access, usage rights and schema behavior before promising a connector.
The screens in detail
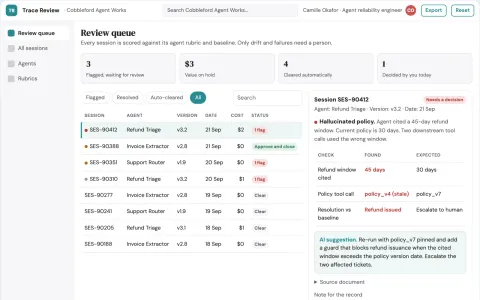
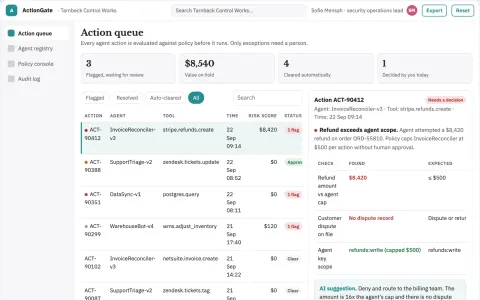
Primary screens: Routing policy editor, Live request monitor, Provider and budget console. Use a table of connected models with health and quota, a central rule canvas, and a right-hand panel for request traces and cost. Let users compare routing paths side by side. Display active, degraded and blocked states. Provide a per-request trace link with the selected model, reason and fallback history. Make the task-specific outcome reviewed routing policy and per-request decision log visible beside its evidence, review state and value baseline.