AI tool
MiMo-V2-Flash
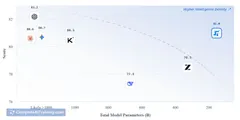
MiMo-V2-Flash (309B MoE, 15B active) is an ultra-fast, efficient foundation LLM by Xiaomi, optimized for advanced reasoning, coding, and agentic workflows and ideal as a general-purpose assistant.
About MiMo-V2-Flash
MiMo-V2-Flash is a 309B Mixture-of-Experts (MoE) language model with about 15B active parameters, released under an open-source Apache 2.0 license. It focuses on reasoning, coding, and agent-style workflows while also serving as a general-purpose assistant.
Review
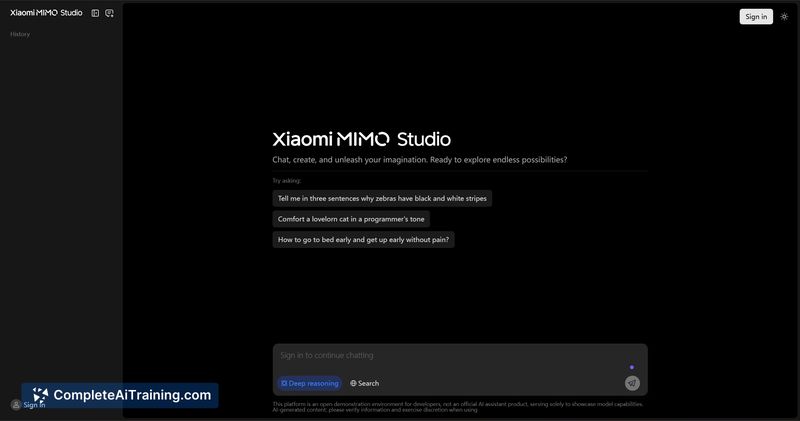
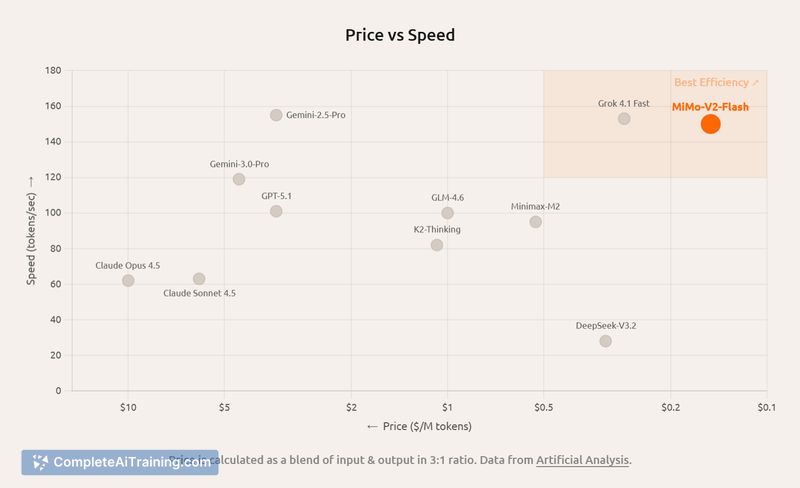
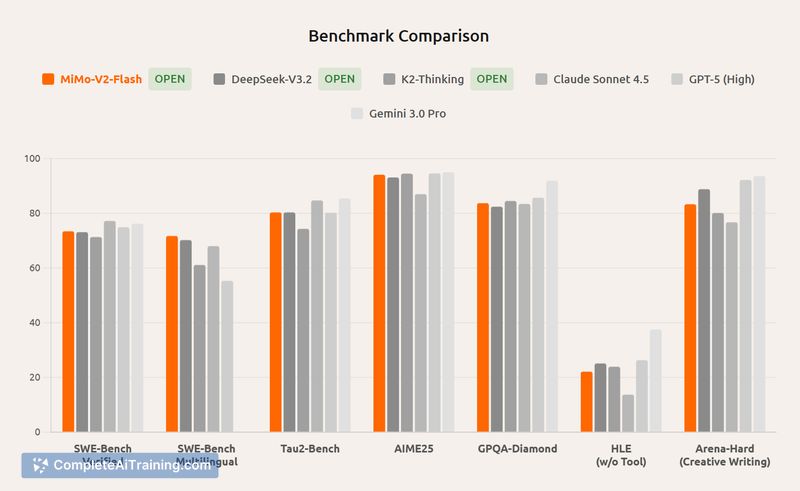
MiMo-V2-Flash stands out for combining a very large sparse architecture with a smaller active parameter footprint, which reduces inference cost compared with a dense 309B model. The availability of base, SFT, and RL-tuned checkpoints, plus a public testing studio and a limited-time free API, make it straightforward to evaluate for a range of development tasks.
Key Features
- 309B MoE architecture with ~15B active parameters for inference efficiency.
- Good performance on reasoning and coding benchmarks; explicitly tuned for agent workflows.
- Multiple checkpoint types available: base, SFT, and RL-tuned versions.
- Open-source release under Apache 2.0, with a public testing studio and temporary free API access.
Pricing and Value
The model itself is distributed under Apache 2.0 and is free to download. There has been a period of free API access for testing; longer-term hosted pricing and commercial terms may vary and should be checked before production use. Value is strongest for users who want a high-capability open model optimized for code and reasoning and who can run or integrate MoE-style inference efficiently.
Pros
- High performance on coding and reasoning tasks thanks to targeted tuning and architecture.
- More inference-efficient than a dense 309B model because only ~15B parameters are active at runtime.
- Open-source license and multiple released checkpoints allow experimentation and fine-tuning.
- Accessible testing options (studio/API) make initial evaluation straightforward.
Cons
- MoE models require specialized inference support and routing logic, which can complicate deployment compared with dense models.
- Operational tooling, long-term hosted pricing, and ecosystem maturity may lag behind more established offerings.
- Model size and architecture add complexity for teams without experience running sparse models.
MiMo-V2-Flash is a strong choice for researchers and developers building coding assistants, reasoning agents, or experiments that benefit from a sparse large-model design. Teams that need simple, out-of-the-box deployment on standard inference stacks may prefer a smaller dense model until MoE runtime support is in place. Overall, it offers good value for those able to handle the additional deployment requirements and who want an open-source, high-capability model to test and extend.
Jobs MiMo-V2-Flash suits
We checked MiMo-V2-Flash against 500+ jobs; these get the most out of it.
Alternatives to MiMo-V2-Flash
Other tools that do the same main job. Our AI compared MiMo-V2-Flash with similar tools and kept the ones you could use instead.